
| REPORT ATTRIBUTE | DETAILS |
|---|---|
| Historical Period | 2020-2023 |
| Base Year | 2024 |
| Forecast Period | 2025-2032 |
| Belgium AI Training Datasets Market Size 2023 | USD13.41 million |
| Belgium AI Training Datasets Market, CAGR | 22.8% |
| Belgium AI Training Datasets Market Size 2032 | USD85.42 million |
Market Overview
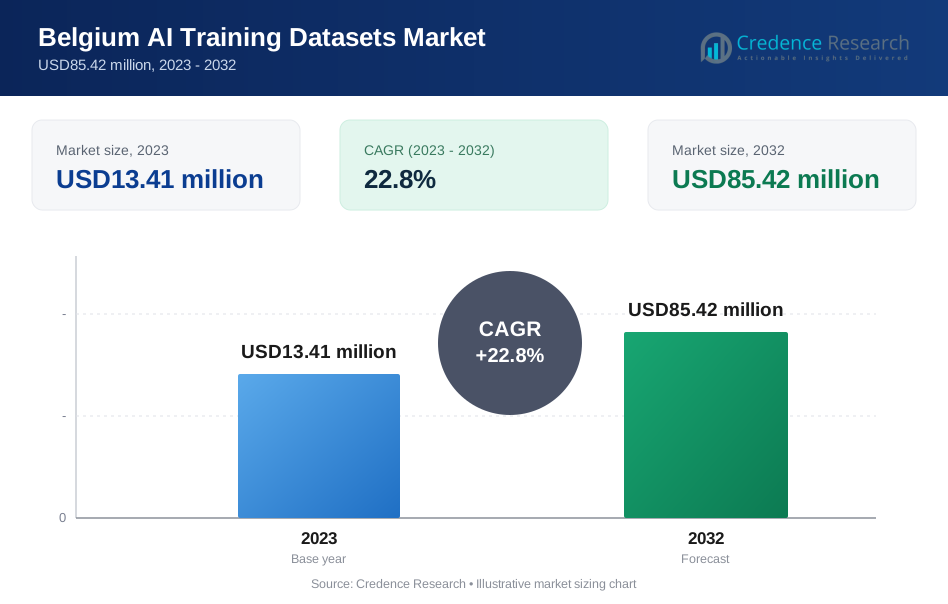
The Belgium AI Training Datasets Market is projected to grow from USD13.41 million in 2023 to an estimated USD85.42 million by 2032, with a compound annual growth rate (CAGR) of 22.8% from 2024 to 2032. This rapid expansion is driven by increasing adoption of AI-driven applications across industries, including healthcare, finance, retail, and autonomous systems.
The market's growth is fueled by rising investments in AI infrastructure, increasing demand for customized and domain-specific datasets, and expanding use of synthetic data to overcome privacy concerns. The integration of automated data labeling, AI-powered annotation tools, and federated learning frameworks is further driving innovation in dataset development. Additionally, stringent EU data privacy regulations are pushing organizations to adopt ethically sourced and compliant AI training datasets, ensuring transparency and data security.
Geographically, Belgium's AI ecosystem is centered around major innovation hubs such as Brussels, Leuven, and Ghent, which host a concentration of tech startups, research institutions, and AI-driven enterprises. The country’s strategic location within Europe enhances collaboration with international AI markets. Key players in the Belgium AI training datasets market include Appen Limited, Scale AI, Cogito Tech, Sama, and Deep Vision Data, all of which are expanding their offerings to meet the growing demand for diverse, high-quality datasets.
Market Insights
- The Belgium AI Training Datasets Market is projected to grow from USD13.41 million in 2023 to USD85.42 million by 2032, with a CAGR of 22.8% from 2024 to 2032, driven by increasing AI adoption across industries.
- Industries such as healthcare, finance, retail, and autonomous systems are increasingly relying on high-quality, domain-specific datasets to enhance AI model accuracy and efficiency.
- The adoption of automated data annotation tools and AI-assisted labeling technologies is improving dataset quality and scalability, supporting the demand for advanced AI applications.
- Strict EU data regulations, including GDPR, require AI training datasets to be ethically sourced and privacy-compliant, leading to challenges in data collection and processing.
- Brussels holds 45.3% of the market, followed by Flanders (38.7%) and Wallonia (16.0%), with major innovation hubs in Brussels, Leuven, and Ghent driving AI research and adoption.
- Companies are increasingly adopting synthetic datasets to address data privacy concerns, reduce bias, and enhance AI model training across various industries.
- Leading players such as Appen Ltd, Scale AI, Cogito Tech, Sama, and Deep Vision Data are expanding their offerings to meet the growing demand for high-quality, regulatory-compliant AI training datasets
Market Drivers
Growing Demand for High-Quality AI Training Data Across Industries
The increasing adoption of AI across Belgian industries like healthcare, finance, retail, manufacturing, and automotive is fueling the demand for high-quality AI training datasets. These sectors leverage AI to enhance operational efficiency, automate processes, and improve decision-making. In healthcare, AI-powered diagnostics rely on medical imaging datasets and patient records. Financial institutions use AI for fraud detection, requiring transactional and behavioral data. Retail and e-commerce integrate AI recommendation engines, necessitating consumer behavior data. The automotive industry uses AI in autonomous vehicle development, demanding extensive image and sensor datasets. As AI adoption expands, the demand for domain-specific, high-quality datasets will continue to rise, driving market growth in Belgium.
Increasing Adoption of AI-Powered Data Annotation and Labeling Solutions
The evolution of AI training datasets is closely tied to advancements in automated data labeling and annotation technologies. Companies in Belgium are increasingly outsourcing dataset annotation or using automated tools that leverage AI for self-improving training datasets. For instance, in computer vision applications, AI-powered annotation tools are streamlining the process of object detection, image classification, and facial recognition dataset creation. Another growing trend is the use of synthetic data generation to overcome challenges related to data scarcity and privacy regulations. Federated learning frameworks are also emerging, enabling organizations to train AI models without centralizing sensitive data, addressing GDPR compliance concerns.
Strong Government Support and AI Research Initiatives
Belgium's AI training datasets market benefits from government-backed AI strategies, research funding, and public-private partnerships. The Belgian government, in alignment with the European Commission’s AI strategy, invests in AI research centers and digital transformation initiatives. The establishment of AI-focused research hubs in cities like Brussels and Ghent has accelerated the demand for high-quality AI training datasets. The Belgian AI Coalition promotes AI adoption across industries while ensuring compliance with GDPR. Belgium's strategic location provides an advantage in AI data exchange and collaboration.
Growing Concerns About Bias, Transparency, and Data Privacy Compliance
As AI adoption expands, concerns about bias, fairness, and data privacy compliance drive the need for better-curated AI training datasets. Regulatory bodies and businesses in Belgium prioritize transparent, unbiased, and privacy-compliant datasets. GDPR compliance has led to increased adoption of anonymization techniques and secure data-sharing platforms. Businesses are implementing explainable AI (XAI) frameworks, which require datasets to be transparent. The push for diverse and representative datasets is gaining traction, with companies investing in dataset augmentation techniques to reduce bias in AI predictions.
Market Trends
Growing Adoption of Synthetic Data for AI Model Training
One of the most prominent trends shaping the Belgium AI Training Datasets Market is the increasing use of synthetic data for AI model training. As AI adoption accelerates across industries, the demand for high-quality, privacy-compliant, and bias-free datasets has surged. However, real-world data is often scarce, expensive, and subject to privacy regulations, particularly in sectors such as healthcare, finance, and autonomous systems. As a result, businesses are turning to synthetic data generation techniques to overcome these challenges.Synthetic data refers to artificially generated datasets that mirror real-world data distributions while eliminating sensitive personal information. Companies in Belgium are increasingly leveraging generative adversarial networks (GANs), variational autoencoders (VAEs), and reinforcement learning-based simulations to create synthetic training datasets. These datasets enhance AI model accuracy while ensuring compliance with stringent data privacy laws, such as the General Data Protection Regulation (GDPR).For instance, in the financial sector, institutions like J.P. Morgan utilize synthetic datasets to enhance their fraud detection algorithms. This approach allows them to train models on data that mimics real customer transactions without exposing sensitive information. In healthcare, organizations such as Roche employ synthetic data to generate medical imaging datasets, refining disease detection models while maintaining patient confidentiality. These examples illustrate how synthetic data not only addresses challenges of data scarcity but also supports the development of effective AI models across various industries in Belgium.
Rising Demand for Domain-Specific and Custom AI Training Datasets
The increasing complexity of AI applications has led to a rising demand for domain-specific and custom AI training datasets tailored to particular industries and use cases. Generic AI datasets often fail to meet the specialized requirements of businesses in healthcare, automotive, e-commerce, finance, and manufacturing, prompting the need for highly curated and contextually relevant datasets.Belgian organizations are increasingly collaborating with AI dataset providers, research institutions, and data labeling firms to develop customized datasets optimized for specific tasks. In the healthcare industry, for example, AI-driven diagnostic models require meticulously annotated radiology images and genomic data to improve detection accuracy for diseases such as cancer. Similarly, financial institutions leverage transactional datasets to enhance AI-powered risk assessment models.In the autonomous vehicle sector, manufacturers are investing in sensor fusion datasets that integrate LiDAR and camera data to improve self-driving vehicle navigation capabilities. The retail sector is also utilizing customer purchase history and sentiment analysis datasets to deliver personalized shopping experiences.As organizations prioritize industry-specific datasets through partnerships with domain experts, the demand for custom datasets is expected to rise further, driving growth in Belgium’s AI training datasets market.
Expansion of AI-Powered Data Annotation and Labeling Solutions
Efficient data annotation and labeling play a crucial role in developing high-performance AI models. As AI applications become more advanced, the need for precise and scalable data labeling solutions has grown significantly in Belgium. Traditionally performed manually, data annotation was time-consuming and labor-intensive. However, advancements in machine learning-assisted annotation and self-supervised learning are transforming how training datasets are prepared.Companies are increasingly adopting AI-driven annotation platforms that utilize natural language processing (NLP) and computer vision to automate dataset labeling. For instance, in computer vision applications, AI-powered labeling tools can automatically detect objects and recognize faces with minimal human oversight. Similarly, NLP-based applications benefit from enhanced accuracy in sentiment analysis and chatbot training through AI-assisted techniques.Additionally, federated learning—a decentralized approach allowing models to be trained across multiple devices without sharing raw data—is gaining traction in Belgium. This method is particularly valuable in industries dealing with sensitive information like healthcare and finance since it enables learning from distributed datasets while ensuring compliance with privacy regulations.As these innovations expand in Belgium’s market, they are expected to significantly enhance the efficiency and quality of AI training datasets.
Increasing Emphasis on Ethical AI and Data Governance
As AI adoption grows, ethical AI development and responsible data governance have become key priorities in Belgium’s AI ecosystem. Regulatory authorities and businesses are focusing on ensuring that AI models are transparent, unbiased, and compliant with data protection laws. This shift has led to an increased demand for ethically sourced and privacy-compliant AI training datasets.With the General Data Protection Regulation (GDPR) imposing stringent restrictions on data collection and usage, companies operating in Belgium are adopting privacy-enhancing technologies (PETs) such as data anonymization and differential privacy. Moreover, concerns about bias have prompted organizations to invest in bias detection techniques to ensure fair outcomes from their AI models.Belgium is actively participating in EU-wide regulatory frameworks aimed at establishing clear guidelines for responsible AI development. For instance, organizations are aligning their training datasets with ethical principles by conducting rigorous audits and fairness assessments to eliminate biases that could lead to discriminatory decisions.This increasing emphasis on ethical practices is driving investments in privacy-conscious datasets and secure data-sharing frameworks. Companies prioritizing ethical AI practices are expected to gain a competitive edge while shaping the trajectory of Belgium’s evolving AI training datasets market.
Market Challenges
Data Privacy Regulations and Compliance Constraints
One of the primary challenges in the Belgium AI Training Datasets Market is navigating the strict data privacy regulations and compliance requirements imposed by the General Data Protection Regulation (GDPR) and other European data governance laws. AI models rely on large volumes of data for training, but accessing, collecting, and processing sensitive user information is heavily restricted due to stringent privacy laws. Organizations must ensure that AI training datasets are legally sourced, anonymized, and free from personally identifiable information (PII) to avoid legal repercussions. The challenge becomes even more pronounced in sectors such as healthcare, finance, and government services, where sensitive data—such as patient records, financial transactions, and citizen information—must be securely stored and ethically utilized. Companies investing in AI training datasets must adopt privacy-enhancing technologies (PETs), including differential privacy, homomorphic encryption, and federated learning, to ensure compliance. However, implementing these solutions increases operational complexity and costs, making it difficult for smaller AI firms and startups to compete with larger enterprises that have the resources to invest in compliance-driven AI solutions. Moreover, cross-border data transfers present another compliance hurdle. Belgium, being part of the European Data Strategy, must align its AI dataset practices with EU-wide AI regulations, which may limit international data collaborations and slow down AI model development. These regulatory constraints restrict access to diverse, high-quality datasets, making it difficult for AI developers to train models effectively while maintaining compliance.
Limited Availability of High-Quality, Bias-Free Training Data
Another significant challenge is the scarcity of high-quality, unbiased, and representative training datasets for AI development. AI models require large, diverse, and well-annotated datasets to achieve high accuracy and generalizability. However, many existing datasets lack sufficient diversity, leading to AI models that exhibit biases in predictions, poor real-world applicability, and ethical concerns. Bias in AI training datasets is particularly evident in applications such as facial recognition, recruitment algorithms, and automated decision-making systems. If datasets are not carefully curated, AI models may perpetuate societal biases, resulting in unfair or discriminatory outcomes. This has led to increased scrutiny from regulatory bodies and stakeholders, forcing companies to invest in bias detection and mitigation strategies. However, ensuring datasets are free from bias requires extensive data collection, curation, and validation processes, which can be both time-consuming and costly. Furthermore, industries such as autonomous vehicles, cybersecurity, and robotics require highly specialized training datasets that are often difficult to source. The lack of open-access domain-specific datasets forces AI developers to create proprietary datasets, which increases development costs and limits market accessibility. Additionally, synthetic data generation, while emerging as a solution, is still not widely adopted across all industries due to concerns regarding its ability to fully replicate real-world complexities. Overall, the limited availability of diverse, high-quality, and bias-free AI training datasets remains a critical barrier to AI development in Belgium. Companies must invest in better data sourcing strategies, leverage AI-assisted data augmentation, and collaborate with research institutions to improve dataset quality while addressing bias-related challenges.
Market Opportunities
Expansion of AI Applications Across Industries Driving Demand for High-Quality Training Datasets
The rapid adoption of artificial intelligence (AI) across multiple industries in Belgium presents a significant market opportunity for AI training datasets. Sectors such as healthcare, finance, retail, manufacturing, and autonomous systems are increasingly integrating AI-driven solutions, necessitating high-quality, domain-specific datasets to enhance model accuracy and efficiency. The healthcare sector is a key area of growth, with AI being leveraged for medical imaging analysis, predictive diagnostics, and personalized treatment recommendations, all of which require well-annotated patient data and clinical datasets. Similarly, the financial sector relies on AI for fraud detection, risk assessment, and automated decision-making, driving demand for secure and privacy-compliant financial datasets. As Belgium strengthens its AI ecosystem with government-backed research initiatives and digital transformation programs, businesses are investing in customized and ethically sourced datasets to align with European Union (EU) regulatory frameworks. The growing need for localized and bias-free datasets also provides an opportunity for dataset providers to offer specialized AI training solutions, fostering innovation and competition in the market.
Rising Adoption of Synthetic Data and AI-Powered Annotation Technologies
The increasing reliance on synthetic data generation and AI-powered annotation tools is creating new opportunities for companies specializing in AI training datasets. Synthetic datasets, which replicate real-world scenarios without exposing sensitive personal data, are becoming essential in industries with strict data privacy regulations, such as healthcare and finance. These datasets allow AI models to be trained effectively while ensuring GDPR compliance and data security. Additionally, AI-driven data labeling and annotation tools are streamlining dataset preparation, making it easier for companies to scale their AI development efforts. Businesses investing in automated annotation platforms and federated learning technologies can capitalize on the growing demand for cost-effective, high-quality, and regulation-compliant AI training datasets, positioning themselves as key players in Belgium’s evolving AI landscape.
Market Segmentation Analysis
By Type
The Belgium AI Training Datasets Market is segmented by type into text, audio, image, video, and others, with each category catering to specific AI applications. Text-based datasets dominate the market due to their extensive use in natural language processing (NLP), sentiment analysis, and chatbots. Companies in sectors such as finance, customer service, and e-commerce are increasingly leveraging text datasets to train AI models for automated customer support, fraud detection, and personalized recommendations.Image datasets are witnessing significant growth, particularly in computer vision applications, including facial recognition, medical imaging, and autonomous vehicles. The healthcare sector is a key consumer, utilizing AI-powered diagnostic tools that rely on annotated medical images for disease detection and radiology analysis. Similarly, the automotive sector is adopting image datasets for self-driving technologies and traffic monitoring systems. Audio and video datasets are also expanding as AI applications in speech recognition, virtual assistants, and surveillance systems gain traction. The rise of smart home assistants, voice biometrics, and automated transcription services is driving demand for high-quality audio datasets in Belgium.
By Deployment Mode
The market is divided into on-premises and cloud-based deployment models. Cloud-based AI training datasets are leading the segment, driven by their scalability, cost-effectiveness, and remote accessibility. Companies are increasingly adopting cloud-based solutions to manage large-scale AI training workloads, facilitate real-time collaboration, and leverage AI-as-a-service platforms. The growing presence of cloud infrastructure providers in Belgium and Europe is accelerating the adoption of cloud-based dataset storage and processing solutions.However, on-premises deployment remains essential for industries requiring higher security, regulatory compliance, and complete control over data. Sectors such as BFSI, healthcare, and government agencies prefer on-premises AI training datasets to ensure data sovereignty, cybersecurity, and compliance with GDPR regulations.
Segments
Based on Type
- Text
- Audio
- Image
- Video
- Others (Sensor and Geo)
Based on Deployment Mode
- On-Premises
- Cloud
Based on End-Users
- IT and Telecommunications
- Retail and Consumer Goods
- Healthcare
- Automotive
- BFSI
- Others (Government and Manufacturing)
Based on Region
- Brussels
- Flanders
- Wallonia
Regional Analysis
Brussels (45.3%)
As the capital of Belgium and a European Union (EU) policy hub, Brussels holds the largest share of the AI training datasets market, accounting for 45.3%. The city is home to AI-focused research institutions, multinational technology firms, and government-backed digital transformation programs that fuel demand for high-quality, domain-specific AI datasets.Brussels' strategic role as an EU regulatory center influences AI data governance policies, creating an environment where privacy-compliant AI training datasets are essential. Key AI applications in the region include automated customer service, fraud detection in the financial sector, and government-led AI adoption initiatives. The presence of AI regulatory bodies, tech incubators, and innovation hubs has attracted investments in GDPR-compliant AI training datasets, further solidifying Brussels' leadership in the market.
Flanders (38.7%)
Flanders, the technology and research powerhouse of Belgium, holds 38.7% of the market, driven by its strong academic ecosystem, AI research funding, and industrial AI applications. Cities such as Leuven and Ghent play a critical role in AI development, with leading universities like KU Leuven and Ghent University pioneering research in computer vision, NLP, and AI-driven healthcare solutions.AI dataset demand in Flanders is particularly high in healthcare, manufacturing, and autonomous systems. The region is home to several AI-focused biotech firms and MedTech companies, which rely on highly curated medical datasets for AI-driven disease detection, robotic-assisted surgery, and predictive analytics. In addition, Flanders is a leader in autonomous vehicle research, requiring sensor fusion datasets, image annotation solutions, and simulation-based AI training to advance self-driving technology.The Flemish government’s AI action plan, which includes significant investments in AI data infrastructure and innovation clusters, is further accelerating market growth in the region. Companies developing AI training datasets in Flanders benefit from strong industry-academic collaborations, ensuring high-quality and domain-specific datasets are available for AI model training.
Key players
- Alphabet Inc. Class A
- Appen Ltd
- Cogito Tech
- com Inc
- Microsoft Corp
- Allegion PLC
- Lionbridge
- SCALE AI
- Sama
- Deep Vision Data
Competitive Analysis
The Belgium AI Training Datasets Market is characterized by the presence of global technology giants, specialized data providers, and AI-driven annotation firms competing to meet the increasing demand for high-quality datasets. Companies like Alphabet Inc., Microsoft Corp., and Amazon.com Inc. dominate the market by offering cloud-based AI dataset solutions, automated data labeling technologies, and AI-powered annotation tools. These industry leaders leverage large-scale infrastructure, extensive R&D capabilities, and partnerships with AI research institutions to maintain a competitive edge. Meanwhile, specialized dataset providers such as Appen Ltd, SCALE AI, Cogito Tech, and Lionbridge focus on customized data annotation, synthetic data generation, and multilingual dataset solutions, catering to diverse industry needs. Sama and Deep Vision Data differentiate themselves by providing scalable, ethically sourced AI training datasets for sectors like autonomous vehicles, healthcare, and NLP applications. As AI adoption increases, competition in accuracy, bias reduction, and compliance-driven datasets will further shape market dynamics.
Recent Developments
- In August 2024, Lionbridge was selected for the 2024 AI in Training Watch List by Training Industry Inc. They offer custom AI-enhanced learning solutions, including multilingual content creation, prompt engineering, and LLM training.
- In September 2024, Sama launched a scalable training platform for AI data annotation, improving tag and shape accuracy and reducing project ramp time. The platform emphasizes data annotation as a stepping stone, investing in its workforce and promoting responsible AI models
Market Concentration and Characteristics
The Belgium AI Training Datasets Market exhibits a moderately concentrated landscape, with global technology leaders and specialized data providers competing to meet the growing demand for high-quality, ethically sourced, and privacy-compliant AI training datasets. The market is driven by the presence of large multinational corporations such as Alphabet Inc., Microsoft Corp., and Amazon.com Inc., which offer cloud-based dataset solutions, automated annotation tools, and AI-powered data processing services. Additionally, specialized firms like Appen Ltd, SCALE AI, and Lionbridge focus on customized dataset creation, synthetic data generation, and industry-specific AI model training. The market is characterized by a strong emphasis on regulatory compliance, particularly with GDPR and EU AI governance frameworks, requiring companies to adopt secure data processing techniques, federated learning, and privacy-enhancing technologies. With increasing investments in domain-specific AI applications across healthcare, finance, retail, and autonomous systems, market participants are focusing on bias-free, high-quality datasets and automated data labeling solutions to gain a competitive edge.
Report Coverage
The research report offers an in-depth analysis based on Type, Deployment Mode, End User and Region. It details leading market players, providing an overview of their business, product offerings, investments, revenue streams, and key applications. Additionally, the report includes insights into the competitive environment, SWOT analysis, current market trends, as well as the primary drivers and constraints. Furthermore, it discusses various factors that have driven market expansion in recent years. The report also explores market dynamics, regulatory scenarios, and technological advancements that are shaping the industry. It assesses the impact of external factors and global economic changes on market growth. Lastly, it provides strategic recommendations for new entrants and established companies to navigate the complexities of the market.
Future Outlook
- Belgium's AI-driven industries, including healthcare, finance, and automotive, will increasingly require customized, high-quality training datasets to enhance AI model accuracy and efficiency.
- Companies will adopt synthetic data generation techniques to overcome privacy concerns and data scarcity, enabling AI models to train effectively while ensuring compliance with GDPR regulations.
- The adoption of automated data labeling tools will accelerate, improving the scalability and accuracy of AI training datasets, particularly in sectors relying on computer vision and NLP applications.
- Regulatory bodies and businesses will continue to focus on reducing bias in AI datasets, ensuring AI models produce fair, transparent, and responsible outcomes in compliance with EU guidelines.
- Federated learning frameworks will gain traction, allowing companies to train AI models across decentralized datasets without exposing sensitive information, ensuring privacy-compliant AI development.
- Belgium’s government and private sector will continue to fund AI research initiatives, fostering innovation in AI dataset creation, annotation techniques, and real-time data processing solutions.
- The use of AI-driven datasets in urban planning, traffic management, and energy optimization will increase, supporting Belgium’s efforts to develop intelligent and sustainable cities.
- As AI adoption expands in customer service and digital transformation, demand for multilingual and culturally adaptive datasets will rise, enhancing AI-driven communication solutions.
- Cloud-based AI training dataset platforms will dominate due to their cost efficiency, scalability, and remote accessibility, enabling businesses to leverage AI without extensive infrastructure investments.
- Belgium’s AI dataset market will witness strong competition from global firms and local startups, with companies focusing on industry-specific solutions, real-time dataset updates, and automated AI training processes.
Request a Free Sample
Fill in your details and we'll send you a free sample report.
- Sample data tables & charts
- Research methodology
Need a Custom Version of This Report?
Tailor the scope, geography, or segments to your exact requirements.
- Custom geography or segment scope
- Direct access to our analyst team
Frequently Asked Questions
What is the market size of the Belgium AI Training Datasets Market in 2023 and 2032, and what is its CAGR?
What factors are driving the growth of the Belgium AI Training Datasets Market?
How are data privacy regulations impacting AI training datasets in Belgium?
Who are the key players in the Belgium AI Training Datasets Market?
Table of Content
Chapter 1. Report Introduction
- 1.1 Report Description & Purpose
- 1.1.1 Report Title & Market Definition
- 1.1.2 Unique Selling Propositions (USP) & Key Differentiators
- 1.1.3 Value Proposition for Stakeholders
- 1.2 Research Objectives
- 1.2.1 Market Sizing Objectives (Volume & Revenue)
- 1.2.2 Segmentation Objectives
- 1.2.3 Competitive Intelligence Objectives
- 1.2.4 Forecast & Scenario Objectives
- 1.3 Report Scope
- 1.3.1 Belgium AI Training Datasets Scope – Types & Subtypes Covered
- 1.3.2 Geographic Scope – Regions & Countries Covered
- 1.3.3 Historical Period, Base Year & Forecast Period (2023; forecast to 2032)
- 1.3.4 Inclusions & Exclusions
- 1.4 HS Code & Classification Framework
- 1.5 Currency, Units & Pricing Basis
- 1.6 Target Stakeholders
- 1.7 Limitations & Assumptions
Chapter 2. Executive Summary
- 2.1 Global Belgium AI Training Datasets Market Snapshot
- 2.1.1 Market Size – Historical (2023) & Forecast (2023-2032) (2023: USD13.41 million → 2032: USD85.42 million)
- 2.1.2 Volume & Revenue – Global Totals
- 2.1.3 Key Market Highlights – Top Five Facts
- 2.2 Belgium AI Training Datasets Market Segmentation Snapshot
- 2.2.1 Market Split by Region – 2023 vs. 2032
- 2.3 Competitive Snapshot
- 2.3.1 Top 10 Players by Revenue Share – 2023
- 2.3.2 Top 10 Players by Volume Share – 2023
- 2.3.3 Recent Strategic Developments (18-Month Summary)
- 2.4 Key Investment Highlights & Strategic Conclusions
Chapter 3. Belgium AI Training Datasets Market Dynamics & Industry Analysis
- 3.1 Market Overview & Context
- 3.1.1 Belgium AI Training Datasets Market Position in the Broader Automotive Value Chain
- 3.1.2 OEM vs. Replacement Market Dynamics
- 3.1.3 Market Maturity & Development Stage by Region
- 3.2 Belgium AI Training Datasets Market Drivers
- 3.3 Belgium AI Training Datasets Market Restraints & Challenges
- 3.4 Belgium AI Training Datasets Market Opportunities
- 3.5 Porter's Five Forces Analysis
- 3.5.1 Threat of New Entrants
- 3.5.2 Bargaining Power of Suppliers
- 3.5.3 Bargaining Power of Buyers
- 3.5.4 Threat of Substitutes
- 3.5.5 Competitive Rivalry – Intensity Assessment
- 3.6 Belgium AI Training Datasets Value Chain Analysis
- 3.6.1 Upstream – Raw Material/Input Suppliers
- 3.6.1.1 Raw Material/Input 1
- 3.6.1.2 Raw Material/Input 2
- 3.6.1.3 Raw Material/Input 3
- 3.6.2 Midstream – Production/Manufacturing/Service Delivery
- 3.6.2.1 Production/Process Overview
- 3.6.2.2 Key Facility Locations & Capacity by Manufacturer
- 3.6.3 Downstream – Distribution & End Consumer
- 3.6.3.1 Primary Channel – B2B/OEM
- 3.6.3.2 Secondary Channels – Dealer, Retail, Online, Direct
- 3.6.4 Value Chain Profitability Analysis
- 3.6.1 Upstream – Raw Material/Input Suppliers
- 3.7 PESTEL Analysis
- 3.7.1 Political Factors
- 3.7.2 Economic Factors
- 3.7.3 Social Factors
- 3.7.4 Technological Factors
- 3.7.5 Environmental Factors
- 3.7.6 Legal Factors
- 3.8 Belgium AI Training Datasets Supply Chain Analysis
- 3.8.1 Raw Material/Input Supply Risk Assessment
- 3.8.2 Manufacturing Concentration Risk (Geographic Exposure)
- 3.8.3 Trade Disruption Impact Analysis
- 3.9 Regulatory & Policy Landscape
Note: The regulatory and policy landscape section covers regulations based on their applicability to the market, Belgium AI Training Datasets category, geography, and scope of the study. Only regulatory frameworks with a material impact on operations, compliance, trade, sustainability, or market access are analyzed in detail.
Chapter 4. Key Investment Pockets & Opportunity Analysis
- 4.1 Belgium AI Training Datasets Market Attractiveness Analysis
- 4.1.1 By Region – Investment Attractiveness Matrix (Volume × CAGR)
- 4.2 Absolute Revenue Growth Opportunity
- 4.2.1 By Region – Absolute USD Growth Through 2032
- 4.3 Incremental Volume Opportunity
- 4.3.1 By Region – Incremental Volume Through 2032
- 4.3.2 Segment – Incremental Volume
- 4.4 Emerging Submarket Opportunity Deep Dive (Subject to Applicability)
- 4.5 Emerging Market Opportunity Scorecards
- 4.5.1 United States
- 4.5.2 Europe
- 4.5.3 Asia
- 4.5.4 Middle East & Africa
Note: Emerging Market Opportunity Scorecards will be included based on relevance and strategic importance. Regions listed are indicative and may vary depending on data availability and market dynamics.
Chapter 5. Belgium AI Training Datasets Import-Export Analysis & Trade Flows
- 5.1 Global Trade Overview
- 5.1.1 Global Export Value by Country (2023)
- 5.1.2 Global Export Volume by Country (2023)
- 5.1.3 Global Import Value by Country (2023)
- 5.1.4 Global Import Volume by Country (2023)
- 5.1.5 Net Trade Balance by Country (2023)
- 5.2 Export Analysis – Segment
- 5.2.1 Type 1 (HS Code)
- 5.2.2 Type 2 (HS Code)
- 5.2.3 Type 3 (HS Code)
- 5.2.4 Type 4 (HS Code)
- 5.2.5 Type 5 (HS Code)
- 5.3 Import Analysis – Segment
- 5.3.1 Type 1 (HS Code)
- 5.3.2 Type 2 (HS Code)
- 5.3.3 Type 3 (HS Code)
- 5.3.4 Type 4 (HS Code)
- 5.3.5 Type 5 (HS Code)
- 5.4 Average Unit Trade Prices
- 5.4.1 Average Export Price – Segment & Country
- 5.4.2 Average Import Price – Segment & Source Country
- 5.4.3 Price Trends (2023)
- 5.5 Key Trade Route Analysis
- 5.5.1 Trade Route 1
- 5.5.2 Trade Route 2
- 5.5.3 Trade Route 3
- 5.5.4 Trade Route 4
- 5.5.5 Trade Route 5
- 5.6 Trade Policy Impact Assessment
- 5.6.1 US Anti-Dumping & Section 301 Tariffs
- 5.6.2 EU Customs Union Impact
- 5.6.3 Major Free Trade Agreements
- 5.6.4 USMCA Rules of Origin
Note: Trade policy analysis will be included only where relevant to the Belgium AI Training Datasets market.
Chapter 6. Competitive Landscape & Company Benchmarking
- 6.1 Belgium AI Training Datasets Market Concentration & Structure
- 6.1.1 Herfindahl-Hirschman Index (HHI) – vs. 2023
- 6.1.2 Tier 1, Tier 2 & Tier 3 Market Structure
- 6.1.3 Global, Regional & Local Player Dynamics
- 6.2 Belgium AI Training Datasets Market Share Analysis – 2023
- 6.2.1 Global Revenue Share by Company
- 6.2.2 Global Volume Share by Company
- 6.2.3 Regional Revenue Share
- 6.2.4 Market Share Evolution ( vs. 2023)
- 6.2.5 OEM Segment Share by Company
- 6.2.6 Replacement Segment Share by Company
- 6.3 Production/Delivery Capacity & Facility Analysis
- 6.3.1 Global Installed Capacity
- 6.3.2 Capacity Utilization Rates
- 6.3.3 Production/Output Volume
- 6.3.4 Facility Locations & Capacity Map
- 6.3.5 Planned Capacity Additions
- 6.4 Belgium AI Training Datasets Competitive Benchmarking Matrix
- 6.4.1 Revenue, Volume, CAGR & Profitability Comparison
- 6.4.2 Channel Revenue Mix
- 6.4.3 Geographic Revenue Exposure
- 6.4.4 R&D Intensity
- 6.4.5 Sustainability Maturity
- 6.5 Strategic Developments in Belgium AI Training Datasets (Last 24 Months)
- 6.5.1 Mergers, Acquisitions & Divestments
- 6.5.2 New Belgium AI Training Datasets Launches
- 6.5.3 Facility Expansions
- 6.5.4 Strategic Alliances, Joint Ventures & Partnerships
- 6.5.5 Distribution Expansion & Market Entry
- 6.5.6 Sustainability & ESG Initiatives
- 6.6 Competitive Strategy Mapping
- 6.6.1 Leader, Challenger, Follower & Niche Classification
- 6.6.2 Pricing Strategy Comparison
- 6.6.3 Channel Strategy Matrix
Note: Strategic developments are included based on their materiality and the availability of reliable information.
Chapter 7. Global Belgium AI Training Datasets Market – By Distribution Channel
- 7.1 Segment Overview
- 7.1.1 Volume & Revenue Split by Channel (2023 & 2032)
- 7.1.2 Channel Mix Evolution (2023-2032)
Chapter 8. Regional Market Analysis – Global Overview
- 8.1 Global Regional Overview
- 8.1.1 Regional Volume Share
- 8.1.2 Regional Revenue Share
- 8.1.3 Regional Volume by Region
- 8.1.4 Regional Revenue by Region
- 8.1.5 Regional Forecast Through 2032
- 8.2 Cross-Regional Segment Analysis
- 8.2.1 By Distribution Channel
- 8.2.2 By Brand/Price Tier
Chapter 9. North America Belgium AI Training Datasets Market
- 9.1 United States
- 9.2 Canada
- 9.3 Mexico
Chapter 10. Europe Belgium AI Training Datasets Market
- 10.1 Germany
- 10.2 France
- 10.3 Italy
- 10.4 United Kingdom
- 10.5 Spain
- 10.6 Poland
- 10.7 Russia
- 10.8 Netherlands
- 10.9 Belgium
- 10.10 Sweden
- 10.11 Denmark
- 10.12 Norway
- 10.13 Rest of Europe
Chapter 11. Asia Pacific Belgium AI Training Datasets Market
- 11.1 China
- 11.2 India
- 11.3 Japan
- 11.4 South Korea
- 11.5 Thailand
- 11.6 Indonesia
- 11.7 Vietnam
- 11.8 Malaysia
- 11.9 Australia
- 11.10 Rest of Asia Pacific
Chapter 12. Latin America Belgium AI Training Datasets Market
- 12.1 Brazil
- 12.2 Argentina
- 12.3 Colombia
- 12.4 Chile
- 12.5 Rest of Latin America
Chapter 13. Middle East Belgium AI Training Datasets Market
- 13.1 Saudi Arabia
- 13.2 United Arab Emirates
- 13.3 Turkey
- 13.4 Israel
- 13.5 Iran
- 13.6 Rest of the Middle East
Chapter 14. Africa Belgium AI Training Datasets Market
- 14.1 South Africa
- 14.2 Egypt
- 14.3 Nigeria
- 14.4 Morocco
- 14.5 Rest of Africa
Chapter 15. Belgium AI Training Datasets Company Profiles
- 15.1 [Company 01]
- 15.1.1 Company Overview
- 15.1.2 Key Management Personnel
- 15.1.3 Products & Services Portfolio
- 15.1.4 Financial Performance
- 15.1.5 Key Market Focus & Geographic Presence
- 15.1.6 Recent Developments & Strategic Initiatives
Note: The company profile list is preliminary and may change based on research findings, market developments, data availability, and client requirements.
Chapter 16. Appendices
- Appendix A – List of Abbreviations & Acronyms
- Appendix B – Industry Classification Code Reference – Full Series
- Appendix C – Production & Capacity Data Tables
- Appendix D – End-Use & Demand Base Tables
- Appendix E – Consumption & Replacement Rate Assumptions
- Appendix F – ASP Reference Tables
- Appendix G – Manufacturing & Facility Database
- Appendix H – Import-Export Data Tables
- Appendix I – Regulatory Summary Tables
- Appendix J – Primary Research Participant List (Anonymized)
- Appendix K – Primary Research Questionnaire Framework
- Appendix L – Data Sources & Bibliography
- Appendix M – Market Size Divergence & Source Comparison
Chapter 17. Research Methodology
- 17.1 Research Framework & Philosophy
- 17.2 Secondary Research – Sources, Hierarchy & Data Extraction
- 17.3 Data Modeling – Bottom-Up & Top-Down Market Sizing
- 17.4 Primary Research – Stakeholder Framework, LOI & Sample Sizes
- 17.5 Forecast Methodology – Regression, Scenario & Sensitivity Analysis
- 17.6 Quality Control – Four-Layer Validation Framework
- 17.7 Limitations & Standard Assumptions
- 17.8 Disclaimer
