
| REPORT ATTRIBUTE | DETAILS |
|---|---|
| Historical Period | 2020-2023 |
| Base Year | 2024 |
| Forecast Period | 2025-2032 |
| Argentina AI Training Datasets Market Size 2023 | USD 18.99 million |
| Argentina AI Training Datasets Market, CAGR | 23.6% |
| Argentina AI Training Datasets MarketSize 2032 | USD 127.83 million |
Market Overview
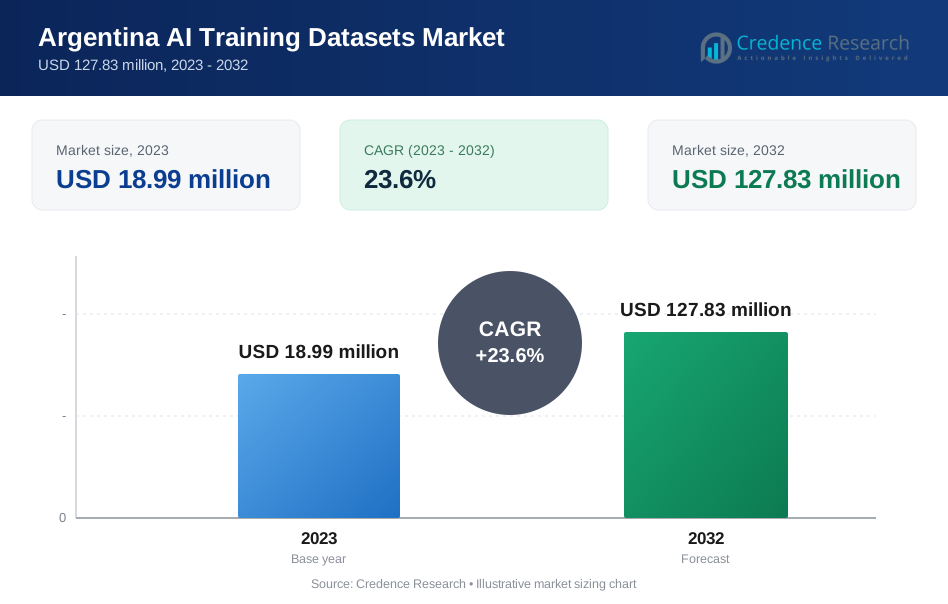
The Argentina AI Training Datasets Market is projected to grow from USD 18.99 million in 2023 to an estimated USD 127.83 million by 2032, registering a compound annual growth rate (CAGR) of 23.6% from 2024 to 2032. This growth is driven by increasing investments in artificial intelligence (AI) applications across multiple industries, including healthcare, finance, and automotive.
Key drivers of the market include the growing digital transformation initiatives, increased reliance on AI-driven analytics, and the rising use of synthetic data for training models. Businesses are increasingly leveraging AI to optimize operations, improve customer experiences, and enhance decision-making. The demand for domain-specific and localized datasets is also rising, especially in sectors such as banking, retail, and e-commerce. Additionally, the increasing emphasis on data privacy and regulatory compliance is shaping the dataset market, driving the need for more secure and ethically sourced AI training data.
Geographically, Buenos Aires and Córdoba are emerging as key hubs for AI innovation, with a strong presence of tech startups, research institutions, and multinational AI firms. The government’s initiatives to promote AI development, including policies supporting AI research and digital infrastructure, are fostering market growth. Key players in the market include Alphabet Inc., Microsoft Corp., Amazon Web Services, Appen Ltd, Lionbridge, and Scale AI, which are actively investing in AI training datasets to support their expanding AI ecosystems.
Market Insight
- The Argentina AI Training Datasets Market is projected to grow from USD 18.99 million in 2023 to USD 127.83 million by 2032, with a CAGR of 23.6%.
- Increasing investments in AI applications across sectors like healthcare, finance, and automotive are driving the demand for structured training datasets.
- Regulatory compliance and the growing emphasis on data privacy are pushing businesses to adopt secure, ethically sourced datasets for AI model development.
- The rising use of synthetic data for model training is a key driver, offering privacy benefits while enhancing dataset diversity.
- Limited access to high-quality, localized datasets hampers model accuracy, particularly for industry-specific applications like natural language processing.
- Buenos Aires and Córdoba are key hubs for AI innovation, with multinational tech firms and research institutions driving market growth in these regions.
- The market is witnessing a shift towards automated data annotation and AI-driven labeling tools to meet growing dataset demands efficiently.
Market Drivers
Rising AI Adoption Across Industries
The Argentina AI Training Datasets Market is significantly influenced by the rising adoption of artificial intelligence across various sectors. Organizations in healthcare, finance, retail, and automotive are actively integrating AI technologies to enhance their operations and improve customer experiences. For instance, in the healthcare sector, AI applications such as diagnostic imaging and personalized medicine rely on large datasets sourced from electronic health records and medical imaging databases. This integration not only enhances diagnostic accuracy but also enables healthcare providers to offer tailored treatment plans based on comprehensive patient data.In finance, companies utilize AI for fraud detection and risk assessment, necessitating access to extensive historical transaction datasets. This capability allows financial institutions to identify unusual patterns and mitigate potential risks effectively. Similarly, the retail and e-commerce sectors leverage AI for customer behavior analysis, employing recommendation engines that analyze consumer data to personalize shopping experiences. Furthermore, Argentina's automotive industry is investing in AI-driven automation and autonomous vehicle technologies, amplifying the demand for high-quality training datasets that support these advanced applications. As these industries evolve, the need for structured, annotated datasets becomes increasingly critical, driving growth in the AI training datasets market within Argentina.
Growing Digital Transformation and Data-Driven Strategies
Argentina is undergoing a significant digital transformation, with businesses and government agencies prioritizing data-driven decision-making. This shift is evident as organizations invest in big data analytics, cloud computing, and AI-driven automation—all of which require large-scale training datasets. AI-powered solutions are being deployed to enhance operational efficiency, optimize supply chain management, and improve customer engagement, making data a critical asset.The Argentine government plays a pivotal role in accelerating this transformation through initiatives promoting AI research, data governance, and digital infrastructure development. For instance, national AI strategies have been introduced to encourage businesses to adopt AI while developing ethical frameworks for its implementation. Public-private partnerships are facilitating open data access and innovation in AI applications, driving the demand for high-quality datasets.Moreover, the integration of AI-powered business intelligence (BI) platforms into enterprise operations helps organizations gain insights into market trends and consumer behavior. The adoption of AI-driven automation across sectors such as banking and logistics further increases the demand for robust training datasets. As organizations continue to shift towards data-centric models, high-quality training datasets become essential for building effective AI applications that drive growth and competitive advantage.
Advancements in AI Technologies and Machine Learning Models
The continuous advancement of AI technologies is propelling the Argentina AI Training Datasets Market forward. Key developments in deep learning, reinforcement learning, and synthetic data generation require large, diverse datasets to improve model accuracy and performance. For instance, synthetic data generation is gaining traction due to its cost-effectiveness and ability to address privacy concerns by creating artificial datasets that mimic real-world data.This technology is particularly beneficial for sensitive industries like healthcare and finance where access to real-world data may be restricted due to regulatory constraints. Additionally, advancements in automated data labeling tools are improving dataset quality while reducing the time required for model training. Companies can now generate well-structured datasets with minimal human intervention through AI-powered annotation platforms.Furthermore, the rising use of AI-powered image recognition and natural language understanding drives companies to invest in comprehensive training datasets tailored for specific use cases. As these applications continue to evolve, businesses seek customized and high-resolution datasets that enhance overall AI performance and adaptability. The growing emphasis on high-quality datasets reflects the need for effective model development in an increasingly competitive landscape.
Increasing Emphasis on Data Privacy, Security, and Ethical AI
As reliance on AI-driven decision-making grows in Argentina, there is an increasing emphasis on data privacy, security, and ethical practices within the industry. Regulatory frameworks such as Argentina’s Personal Data Protection Law influence how companies manage their AI training datasets. Businesses must ensure secure and ethically sourced data for model development to comply with these regulations.In response to privacy concerns, there has been a notable shift toward privacy-enhancing technologies (PETs) like federated learning and differential privacy. These innovations enable organizations to train models on decentralized datasets without compromising sensitive information. This trend reshapes dataset management strategies while encouraging investments in secure, privacy-compliant training datasets.Moreover, ethical considerations are gaining importance as companies prioritize bias-free datasets to ensure fair decision-making processes within their AI models. By adopting diverse and inclusive datasets, organizations can reduce algorithmic bias while enhancing model reliability. Initiatives promoting transparent governance further reinforce the demand for high-quality datasets that align with ethical standards. As regulations evolve alongside ethical considerations, businesses must adapt their practices accordingly to thrive in the Argentina AI Training Datasets Market.
Market Trends
Increasing Adoption of Synthetic Data for AI Model Training
One of the most significant trends in the Argentina AI Training Datasets Market is the rising adoption of synthetic data for AI model training. As businesses and AI researchers seek to overcome the challenges of limited, biased, or privacy-sensitive real-world data, synthetic data is emerging as a viable alternative. For instance, in healthcare AI, synthetic patient records are utilized to train AI models for medical diagnosis and predictive analytics without compromising patient confidentiality. Similarly, in autonomous driving applications, AI models rely on synthetic road and traffic simulations to improve self-driving algorithms without extensive real-world testing. This trend is particularly beneficial in finance, where AI-driven fraud detection models require vast datasets of financial transactions. By using synthetic transaction datasets, financial institutions can train their models while ensuring compliance with data protection regulations such as Argentina’s Personal Data Protection Law. The growing use of synthetic data generation platforms is expected to accelerate adoption across industries, increasing AI model scalability and improving data diversity.
Expansion of AI Training Data Annotation and Labeling Services
As the demand for high-quality AI training datasets continues to grow, there is a surge in demand for data annotation and labeling services across Argentina. AI models require precisely labeled datasets to enhance the accuracy and efficiency of machine learning algorithms, particularly in areas such as computer vision, speech recognition, and sentiment analysis. For instance, in computer vision applications, extensive image and video annotation is required for tasks like facial recognition and object detection. AI-driven annotation tools equipped with bounding boxes, polygon segmentation, and keypoint annotation streamline dataset labeling for these applications. Additionally, multilingual AI dataset annotation is emerging as a critical trend due to Argentina’s diverse linguistic landscape. The increasing deployment of Spanish-language AI chatbots and speech recognition systems drives demand for localized dataset labeling. With the rise of outsourcing opportunities in AI dataset labeling, Argentina’s role as a hub for these services is expected to grow, making AI model training more cost-effective and efficient.
Integration of Privacy-Preserving AI Techniques in Dataset Development
As AI models become more sophisticated and widely adopted, concerns regarding data privacy and ethical development are intensifying. In response, AI dataset providers in Argentina are increasingly incorporating privacy-preserving techniques to ensure compliance with regulations while maintaining model accuracy. For instance, federated learning allows AI models to be trained across multiple decentralized datasets without sharing raw data—beneficial for industries like healthcare and finance that handle sensitive information. Additionally, differential privacy techniques introduce statistical noise into datasets to protect individual user identities during analysis. Furthermore, Argentina's evolving regulatory landscape encourages responsible practices in dataset development. Businesses are required to adhere to ethical governance principles ensuring that training datasets are bias-free and representative. As organizations prioritize ethical development and compliance, the demand for privacy-enhancing dataset solutions is expected to grow, driving innovation in secure AI training datasets that respect user privacy.
Growth of AI Training Datasets in Edge Computing and IoT Applications
The increasing adoption of edge AI and Internet of Things (IoT) technologies is creating new opportunities for AI training dataset development in Argentina. As businesses deploy AI-powered edge devices—such as smart cameras and industrial sensors—the demand for real-time localized datasets is growing. For instance, in manufacturing, predictive maintenance systems leverage real-time IoT sensor data to detect equipment failures and optimize production efficiency; these systems require constantly updated sensor-specific training datasets to improve anomaly detection capabilities. Similarly, smart retail applications utilize video-based datasets for customer behavior analysis and loss prevention. Furthermore, Argentina’s smart agriculture sector is adopting precision farming techniques that rely on real-time datasets collected from IoT-enabled sensors and drones. These models enhance yield prediction and pest detection while driving the need for specialized training datasets tailored for agricultural applications. As businesses increasingly shift toward edge AI deployment, the demand for low-latency device-optimized datasets will continue to rise, positioning Argentina as a key market for these innovations.
Market Challenges
Limited Availability of High-Quality and Localized Training Data
One of the most pressing challenges in the Argentina AI Training Datasets Market is the limited availability of high-quality and localized training data. AI models require diverse, well-annotated datasets to ensure accuracy and efficiency in real-world applications. However, Argentina faces constraints in dataset accessibility, particularly in industry-specific and Spanish-language AI datasets, which are essential for applications such as natural language processing (NLP), sentiment analysis, and voice recognition. The shortage of domain-specific datasets for industries such as finance, healthcare, and retail hinders the development of AI models tailored to Argentina’s regulatory, cultural, and economic environment. Many AI firms rely on international datasets, which may not accurately reflect local consumer behavior, language nuances, or business practices, reducing AI effectiveness. Furthermore, data fragmentation across multiple private and public institutions makes it difficult for AI developers to consolidate and standardize datasets for training. Additionally, manual data annotation remains a challenge, as it is time-consuming, labor-intensive, and costly. While AI-powered automated labeling solutions are emerging, their adoption is still in the early stages in Argentina. Without access to high-quality, well-annotated training data, AI models may suffer from bias, lower accuracy, and poor generalization, limiting their commercial viability.
Stringent data privacy laws and compliance requirements present another major challenge for the Argentina AI Training Datasets Market. The Personal Data Protection Law (Ley de Protección de Datos Personales) imposes strict regulations on data collection, processing, and storage, requiring AI firms to implement robust data security and anonymization practices. Compliance with these regulations increases operational complexity and costs, as businesses must ensure that training datasets meet legal and ethical standards. Moreover, cross-border data transfer restrictions pose challenges for multinational AI firms operating in Argentina. Companies developing AI-driven analytics, fraud detection, and healthcare applications must navigate complex legal frameworks to access, share, and process data, limiting dataset availability for AI model training. The growing emphasis on ethical AI and bias reduction further necessitates investment in privacy-enhancing technologies (PETs), federated learning, and differential privacy techniques, increasing costs for AI developers. As regulatory compliance requirements evolve, AI firms in Argentina must adopt secure, transparent, and ethically sourced training datasets while maintaining model performance and scalability. These privacy and compliance constraints present significant hurdles to AI dataset availability, innovation, and market expansion.
Market Opportunities
Expansion of Localized AI Solutions for Diverse Industries
One of the primary opportunities in the Argentina AI Training Datasets Market lies in the growing demand for localized AI solutions across various industries. As AI adoption continues to rise, there is an increasing need for datasets that reflect Argentina’s unique cultural, economic, and linguistic characteristics. Industries such as finance, healthcare, agriculture, and retail are seeking AI models that can cater to the specific needs of local markets. For instance, banking and fintech companies require datasets tailored to Argentina’s financial systems and consumer behavior, while the healthcare sector demands data specific to local health conditions and patient demographics. This presents a significant opportunity for businesses and data providers to develop customized, domain-specific, and regionally relevant training datasets. By addressing this gap, companies can enhance the performance of AI models, improve their accuracy in real-world applications, and offer highly relevant solutions to local businesses. The growth of AI-powered smart agriculture and AI-driven retail analytics in Argentina also represents opportunities for dataset providers to expand their offerings, ensuring high-quality, localized training data for industries investing in AI innovation.
Government Initiatives and Investment in AI Research
The Argentine government’s increasing focus on AI development and digital transformation provides a strong growth opportunity for the AI training datasets market. Government initiatives supporting AI research, innovation, and data infrastructure are creating an ecosystem conducive to the development of high-quality AI datasets. Investments in public-private partnerships and open data initiatives are expected to enhance the availability of relevant datasets for AI model development. As Argentina strengthens its AI regulatory framework, the demand for secure, compliant, and ethical datasets will rise, opening avenues for businesses to lead in the creation of privacy-compliant AI training datasets.
Market Segmentation Analysis
By Type
The AI training datasets in Argentina are primarily categorized into text, audio, image, video, and others. The text datasets segment holds a significant share, driven by the growing demand for natural language processing (NLP) applications such as chatbots, sentiment analysis, and machine translation. As more businesses adopt voice-activated systems, the audio datasets segment is also gaining momentum, particularly in industries like healthcare (for medical transcription) and automotive (for voice assistants in vehicles). The image datasets segment is fueled by the expansion of computer vision applications in industries such as retail, automotive, and security, where AI models require large, labeled image data for tasks such as facial recognition and object detection. Similarly, the video datasets segment is growing with the demand for video analytics and surveillance systems, which require vast amounts of annotated video data for AI model training. The others category includes datasets for sensor data and IoT-based applications, particularly in smart agriculture and smart cities.
By Deployment Mode
The market is also segmented by deployment mode into on-premises and cloud. Cloud-based deployments are gaining significant traction due to the increasing adoption of cloud computing and data storage solutions. Cloud platforms offer businesses flexibility, scalability, and cost-effectiveness, enabling them to manage and process large datasets for AI model training. The on-premises deployment model is still prevalent among companies with strict data privacy and security concerns, particularly in sectors like banking and healthcare. However, the shift towards cloud computing is evident as businesses look for more efficient and scalable ways to manage AI datasets.
Segments
Based on Type
- Text
- Audio
- Image
- Video
- Others (Sensor and Geo)
Based on Deployment Mode
- On-Premises
- Cloud
Based on End-Users
- IT and Telecommunications
- Retail and Consumer Goods
- Healthcare
- Automotive
- BFSI
- Others (Government and Manufacturing)
Based on Region
- Buenos Aires
- Córdoba
- Santa Fe
- Other Regions
Regional Analysis
Buenos Aires (45-50%)
As the capital city, Buenos Aires holds the largest share of the Argentina AI Training Datasets Market, accounting for approximately 45-50% of the market. The city serves as a hub for AI innovation, hosting numerous multinational tech companies, AI research institutions, and startups. Buenos Aires is central to the development and implementation of AI-driven solutions across various industries, including IT and telecommunications, finance, and healthcare. The region's robust infrastructure, access to skilled labor, and proximity to key stakeholders make it the focal point for AI training dataset development. Furthermore, Buenos Aires' government-led initiatives, such as digital transformation policies and AI research funding, continue to foster a favorable ecosystem for AI and data-driven technologies.
Córdoba (25-30%)
Córdoba is a growing center for AI adoption, particularly in the sectors of automotive, agriculture, and manufacturing, contributing around 25-30% to the overall market. The region benefits from a strong industrial base, with companies focusing on smart manufacturing and AI-driven automotive technologies. The smart agriculture sector, in particular, is a significant driver in Córdoba, where AI models leveraging datasets for precision farming and crop monitoring are becoming increasingly common. Local universities and research centers are also playing a crucial role in AI developments, further supporting the demand for high-quality training datasets. Córdoba's strong industrial and academic collaboration accelerates the growth of the AI training dataset market, positioning it as a significant contributor to Argentina's AI ecosystem.
Key players
- Alphabet Inc Class A
- Appen Ltd
- Cogito Tech
- com Inc
- Microsoft Corp
- Allegion PLC
- Lionbridge
- SCALE AI
- Sama
- Deep Vision Data
Competitive Analysis
The Argentina AI Training Datasets Market is highly competitive, with several key players dominating the space. Companies like Alphabet Inc Class A, Microsoft Corp, and Amazon.com Inc leverage their global presence and technological infrastructure to provide extensive AI training datasets for diverse industries. Appen Ltd, Lionbridge, and SCALE AI are well-positioned as prominent players specializing in high-quality, annotated datasets for machine learning applications, often with a focus on large-scale and multilingual data. Emerging players like Cogito Tech and Deep Vision Data offer specialized AI dataset services, targeting niche applications in industries like healthcare and automotive. Sama and Allegion PLC are also competitive in areas of data privacy and ethically sourced datasets, ensuring compliance with regulations. The competition is centered around dataset quality, compliance with data privacy laws, and the ability to provide industry-specific, tailored datasets, with a growing focus on automated annotation and labeling technologies.
Recent Developments
- In February 2025, Google continues to enhance its dataset offerings through Google Cloud AutoML and Dataset Search, focusing on providing diverse datasets for machine learning applications.
- In January 2025, Appen has been actively expanding its crowdsourced data collection services to improve image and speech data quality for AI training purposes.
- In December 2024, Amazon Web Services (AWS) has been enhancing its SageMaker Ground Truth service to provide more efficient labeling services for machine learning models.
- In February 2025, Microsoft Azure is expanding its machine learning capabilities with new tools aimed at optimizing dataset management and enhancing data labeling processes4.
Market Concentration and Characteristics
The Argentina AI Training Datasets Market exhibits moderate market concentration, with a mix of global technology giants and specialized local firms. Leading players like Alphabet Inc Class A, Amazon.com Inc, and Microsoft Corp dominate the market due to their vast resources and technological expertise, offering extensive, high-quality datasets across various industries. However, smaller, more agile companies such as Appen Ltd, SCALE AI, and Lionbridge are gaining traction by focusing on customized datasets and automated data annotation services. The market is characterized by a growing demand for industry-specific and localized datasets, especially in sectors like healthcare, automotive, and agriculture. As the demand for AI training data expands, competition is intensifying around providing high-quality, ethically sourced datasets that comply with local data privacy regulations. The market is evolving with increasing investment in automation, data privacy technologies, and AI-enhanced data labeling platforms.
Report Coverage
The research report offers an in-depth analysis based on Type, Deployment Mode, End User and Region. It details leading market players, providing an overview of their business, product offerings, investments, revenue streams, and key applications. Additionally, the report includes insights into the competitive environment, SWOT analysis, current market trends, as well as the primary drivers and constraints. Furthermore, it discusses various factors that have driven market expansion in recent years. The report also explores market dynamics, regulatory scenarios, and technological advancements that are shaping the industry. It assesses the impact of external factors and global economic changes on market growth. Lastly, it provides strategic recommendations for new entrants and established companies to navigate the complexities of the market.
Future Outlook
- The demand for AI training datasets will continue to rise as AI adoption expands in sectors such as healthcare, finance, and automotive.
- AI companies will prioritize region-specific datasets, particularly in Spanish language processing and local market behaviors, to enhance model accuracy in Argentina.
- The use of synthetic data will grow significantly, enabling the development of AI models without compromising data privacy or dealing with real-world data limitations.
- AI-driven automated annotation tools will become more prevalent, reducing costs and improving the speed of dataset creation while maintaining accuracy.
- Privacy-enhancing technologies such as federated learning and differential privacy will become critical in ensuring data security and compliance with data protection regulations.
- Collaboration between government bodies and private firms will accelerate the creation of open, high-quality datasets, fostering innovation in AI-driven solutions.
- Industries like automotive, smart agriculture, and BFSI will drive the need for highly specialized datasets to improve AI model performance in unique applications.
- As cloud adoption increases, businesses will leverage cloud computing for scalable storage and processing of large AI training datasets, reducing infrastructure costs.
- Argentina's growing emphasis on AI research and development programs will lead to the creation of more diverse and comprehensive datasets for a range of applications.
- The increasing availability of skilled AI professionals in Argentina will foster the growth of AI-focused startups, enhancing the demand for locally sourced and tailored training datasets.
Request a Free Sample
Fill in your details and we'll send you a free sample report.
- Sample data tables & charts
- Research methodology
Need a Custom Version of This Report?
Tailor the scope, geography, or segments to your exact requirements.
- Custom geography or segment scope
- Direct access to our analyst team
Frequently Asked Questions
What is the market size of the Argentina AI Training Datasets Market in 2023 and 2032, and what is the expected CAGR?
What are the key drivers of the Argentina AI Training Datasets Market?
How are AI regulations influencing the Argentina AI Training Datasets Market?
What are the key regions contributing to the growth of AI training datasets in Argentina?
Table of Content
Chapter 1. Report Introduction
- 1.1 Report Description & Purpose
- 1.1.1 Report Title & Market Definition
- 1.1.2 Unique Selling Propositions (USP) & Key Differentiators
- 1.1.3 Value Proposition for Stakeholders
- 1.2 Research Objectives
- 1.2.1 Market Sizing Objectives (Volume & Revenue)
- 1.2.2 Segmentation Objectives
- 1.2.3 Competitive Intelligence Objectives
- 1.2.4 Forecast & Scenario Objectives
- 1.3 Report Scope
- 1.3.1 Argentina AI Training Datasets Scope – Types & Subtypes Covered
- 1.3.2 Geographic Scope – Regions & Countries Covered
- 1.3.3 Historical Period, Base Year & Forecast Period (2023; forecast to 2032)
- 1.3.4 Inclusions & Exclusions
- 1.4 HS Code & Classification Framework
- 1.5 Currency, Units & Pricing Basis
- 1.6 Target Stakeholders
- 1.7 Limitations & Assumptions
Chapter 2. Executive Summary
- 2.1 Global Argentina AI Training Datasets Market Snapshot
- 2.1.1 Market Size – Historical (2023) & Forecast (2023-2032) (2023: USD 18.99 million → 2032: USD 127.83 million)
- 2.1.2 Volume & Revenue – Global Totals
- 2.1.3 Key Market Highlights – Top Five Facts
- 2.2 Argentina AI Training Datasets Market Segmentation Snapshot
- 2.2.1 Market Split by Region – 2023 vs. 2032
- 2.3 Competitive Snapshot
- 2.3.1 Top 10 Players by Revenue Share – 2023
- 2.3.2 Top 10 Players by Volume Share – 2023
- 2.3.3 Recent Strategic Developments (18-Month Summary)
- 2.4 Key Investment Highlights & Strategic Conclusions
Chapter 3. Argentina AI Training Datasets Market Dynamics & Industry Analysis
- 3.1 Market Overview & Context
- 3.1.1 Argentina AI Training Datasets Market Position in the Broader Automotive Value Chain
- 3.1.2 OEM vs. Replacement Market Dynamics
- 3.1.3 Market Maturity & Development Stage by Region
- 3.2 Argentina AI Training Datasets Market Drivers
- 3.3 Argentina AI Training Datasets Market Restraints & Challenges
- 3.4 Argentina AI Training Datasets Market Opportunities
- 3.5 Porter's Five Forces Analysis
- 3.5.1 Threat of New Entrants
- 3.5.2 Bargaining Power of Suppliers
- 3.5.3 Bargaining Power of Buyers
- 3.5.4 Threat of Substitutes
- 3.5.5 Competitive Rivalry – Intensity Assessment
- 3.6 Argentina AI Training Datasets Value Chain Analysis
- 3.6.1 Upstream – Raw Material/Input Suppliers
- 3.6.1.1 Raw Material/Input 1
- 3.6.1.2 Raw Material/Input 2
- 3.6.1.3 Raw Material/Input 3
- 3.6.2 Midstream – Production/Manufacturing/Service Delivery
- 3.6.2.1 Production/Process Overview
- 3.6.2.2 Key Facility Locations & Capacity by Manufacturer
- 3.6.3 Downstream – Distribution & End Consumer
- 3.6.3.1 Primary Channel – B2B/OEM
- 3.6.3.2 Secondary Channels – Dealer, Retail, Online, Direct
- 3.6.4 Value Chain Profitability Analysis
- 3.6.1 Upstream – Raw Material/Input Suppliers
- 3.7 PESTEL Analysis
- 3.7.1 Political Factors
- 3.7.2 Economic Factors
- 3.7.3 Social Factors
- 3.7.4 Technological Factors
- 3.7.5 Environmental Factors
- 3.7.6 Legal Factors
- 3.8 Argentina AI Training Datasets Supply Chain Analysis
- 3.8.1 Raw Material/Input Supply Risk Assessment
- 3.8.2 Manufacturing Concentration Risk (Geographic Exposure)
- 3.8.3 Trade Disruption Impact Analysis
- 3.9 Regulatory & Policy Landscape
Note: The regulatory and policy landscape section covers regulations based on their applicability to the market, Argentina AI Training Datasets category, geography, and scope of the study. Only regulatory frameworks with a material impact on operations, compliance, trade, sustainability, or market access are analyzed in detail.
Chapter 4. Key Investment Pockets & Opportunity Analysis
- 4.1 Argentina AI Training Datasets Market Attractiveness Analysis
- 4.1.1 By Region – Investment Attractiveness Matrix (Volume × CAGR)
- 4.2 Absolute Revenue Growth Opportunity
- 4.2.1 By Region – Absolute USD Growth Through 2032
- 4.3 Incremental Volume Opportunity
- 4.3.1 By Region – Incremental Volume Through 2032
- 4.3.2 Segment – Incremental Volume
- 4.4 Emerging Submarket Opportunity Deep Dive (Subject to Applicability)
- 4.5 Emerging Market Opportunity Scorecards
- 4.5.1 United States
- 4.5.2 Europe
- 4.5.3 Asia
- 4.5.4 Middle East & Africa
Note: Emerging Market Opportunity Scorecards will be included based on relevance and strategic importance. Regions listed are indicative and may vary depending on data availability and market dynamics.
Chapter 5. Argentina AI Training Datasets Import-Export Analysis & Trade Flows
- 5.1 Global Trade Overview
- 5.1.1 Global Export Value by Country (2023)
- 5.1.2 Global Export Volume by Country (2023)
- 5.1.3 Global Import Value by Country (2023)
- 5.1.4 Global Import Volume by Country (2023)
- 5.1.5 Net Trade Balance by Country (2023)
- 5.2 Export Analysis – Segment
- 5.2.1 Type 1 (HS Code)
- 5.2.2 Type 2 (HS Code)
- 5.2.3 Type 3 (HS Code)
- 5.2.4 Type 4 (HS Code)
- 5.2.5 Type 5 (HS Code)
- 5.3 Import Analysis – Segment
- 5.3.1 Type 1 (HS Code)
- 5.3.2 Type 2 (HS Code)
- 5.3.3 Type 3 (HS Code)
- 5.3.4 Type 4 (HS Code)
- 5.3.5 Type 5 (HS Code)
- 5.4 Average Unit Trade Prices
- 5.4.1 Average Export Price – Segment & Country
- 5.4.2 Average Import Price – Segment & Source Country
- 5.4.3 Price Trends (2023)
- 5.5 Key Trade Route Analysis
- 5.5.1 Trade Route 1
- 5.5.2 Trade Route 2
- 5.5.3 Trade Route 3
- 5.5.4 Trade Route 4
- 5.5.5 Trade Route 5
- 5.6 Trade Policy Impact Assessment
- 5.6.1 US Anti-Dumping & Section 301 Tariffs
- 5.6.2 EU Customs Union Impact
- 5.6.3 Major Free Trade Agreements
- 5.6.4 USMCA Rules of Origin
Note: Trade policy analysis will be included only where relevant to the Argentina AI Training Datasets market.
Chapter 6. Competitive Landscape & Company Benchmarking
- 6.1 Argentina AI Training Datasets Market Concentration & Structure
- 6.1.1 Herfindahl-Hirschman Index (HHI) – vs. 2023
- 6.1.2 Tier 1, Tier 2 & Tier 3 Market Structure
- 6.1.3 Global, Regional & Local Player Dynamics
- 6.2 Argentina AI Training Datasets Market Share Analysis – 2023
- 6.2.1 Global Revenue Share by Company
- 6.2.2 Global Volume Share by Company
- 6.2.3 Regional Revenue Share
- 6.2.4 Market Share Evolution ( vs. 2023)
- 6.2.5 OEM Segment Share by Company
- 6.2.6 Replacement Segment Share by Company
- 6.3 Production/Delivery Capacity & Facility Analysis
- 6.3.1 Global Installed Capacity
- 6.3.2 Capacity Utilization Rates
- 6.3.3 Production/Output Volume
- 6.3.4 Facility Locations & Capacity Map
- 6.3.5 Planned Capacity Additions
- 6.4 Argentina AI Training Datasets Competitive Benchmarking Matrix
- 6.4.1 Revenue, Volume, CAGR & Profitability Comparison
- 6.4.2 Channel Revenue Mix
- 6.4.3 Geographic Revenue Exposure
- 6.4.4 R&D Intensity
- 6.4.5 Sustainability Maturity
- 6.5 Strategic Developments in Argentina AI Training Datasets (Last 24 Months)
- 6.5.1 Mergers, Acquisitions & Divestments
- 6.5.2 New Argentina AI Training Datasets Launches
- 6.5.3 Facility Expansions
- 6.5.4 Strategic Alliances, Joint Ventures & Partnerships
- 6.5.5 Distribution Expansion & Market Entry
- 6.5.6 Sustainability & ESG Initiatives
- 6.6 Competitive Strategy Mapping
- 6.6.1 Leader, Challenger, Follower & Niche Classification
- 6.6.2 Pricing Strategy Comparison
- 6.6.3 Channel Strategy Matrix
Note: Strategic developments are included based on their materiality and the availability of reliable information.
Chapter 7. Global Argentina AI Training Datasets Market – By Distribution Channel
- 7.1 Segment Overview
- 7.1.1 Volume & Revenue Split by Channel (2023 & 2032)
- 7.1.2 Channel Mix Evolution (2023-2032)
Chapter 8. Regional Market Analysis – Global Overview
- 8.1 Global Regional Overview
- 8.1.1 Regional Volume Share
- 8.1.2 Regional Revenue Share
- 8.1.3 Regional Volume by Region
- 8.1.4 Regional Revenue by Region
- 8.1.5 Regional Forecast Through 2032
- 8.2 Cross-Regional Segment Analysis
- 8.2.1 By Distribution Channel
- 8.2.2 By Brand/Price Tier
Chapter 9. North America Argentina AI Training Datasets Market
- 9.1 United States
- 9.2 Canada
- 9.3 Mexico
Chapter 10. Europe Argentina AI Training Datasets Market
- 10.1 Germany
- 10.2 France
- 10.3 Italy
- 10.4 United Kingdom
- 10.5 Spain
- 10.6 Poland
- 10.7 Russia
- 10.8 Netherlands
- 10.9 Belgium
- 10.10 Sweden
- 10.11 Denmark
- 10.12 Norway
- 10.13 Rest of Europe
Chapter 11. Asia Pacific Argentina AI Training Datasets Market
- 11.1 China
- 11.2 India
- 11.3 Japan
- 11.4 South Korea
- 11.5 Thailand
- 11.6 Indonesia
- 11.7 Vietnam
- 11.8 Malaysia
- 11.9 Australia
- 11.10 Rest of Asia Pacific
Chapter 12. Latin America Argentina AI Training Datasets Market
- 12.1 Brazil
- 12.2 Argentina
- 12.3 Colombia
- 12.4 Chile
- 12.5 Rest of Latin America
Chapter 13. Middle East Argentina AI Training Datasets Market
- 13.1 Saudi Arabia
- 13.2 United Arab Emirates
- 13.3 Turkey
- 13.4 Israel
- 13.5 Iran
- 13.6 Rest of the Middle East
Chapter 14. Africa Argentina AI Training Datasets Market
- 14.1 South Africa
- 14.2 Egypt
- 14.3 Nigeria
- 14.4 Morocco
- 14.5 Rest of Africa
Chapter 15. Argentina AI Training Datasets Company Profiles
- 15.1 [Company 01]
- 15.1.1 Company Overview
- 15.1.2 Key Management Personnel
- 15.1.3 Products & Services Portfolio
- 15.1.4 Financial Performance
- 15.1.5 Key Market Focus & Geographic Presence
- 15.1.6 Recent Developments & Strategic Initiatives
Note: The company profile list is preliminary and may change based on research findings, market developments, data availability, and client requirements.
Chapter 16. Appendices
- Appendix A – List of Abbreviations & Acronyms
- Appendix B – Industry Classification Code Reference – Full Series
- Appendix C – Production & Capacity Data Tables
- Appendix D – End-Use & Demand Base Tables
- Appendix E – Consumption & Replacement Rate Assumptions
- Appendix F – ASP Reference Tables
- Appendix G – Manufacturing & Facility Database
- Appendix H – Import-Export Data Tables
- Appendix I – Regulatory Summary Tables
- Appendix J – Primary Research Participant List (Anonymized)
- Appendix K – Primary Research Questionnaire Framework
- Appendix L – Data Sources & Bibliography
- Appendix M – Market Size Divergence & Source Comparison
Chapter 17. Research Methodology
- 17.1 Research Framework & Philosophy
- 17.2 Secondary Research – Sources, Hierarchy & Data Extraction
- 17.3 Data Modeling – Bottom-Up & Top-Down Market Sizing
- 17.4 Primary Research – Stakeholder Framework, LOI & Sample Sizes
- 17.5 Forecast Methodology – Regression, Scenario & Sensitivity Analysis
- 17.6 Quality Control – Four-Layer Validation Framework
- 17.7 Limitations & Standard Assumptions
- 17.8 Disclaimer
