
| REPORT ATTRIBUTE | DETAILS |
|---|---|
| Historical Period | 2019-2022 |
| Base Year | 2023 |
| Forecast Period | 2024-2032 |
| Poland AI Training Datasets Market Size 2023 | USD 13.54 Million |
| Poland AI Training Datasets Market, CAGR | 20.6% |
| Poland AI Training Datasets Market Size 2032 | USD 73.58 Million |
Market Overview
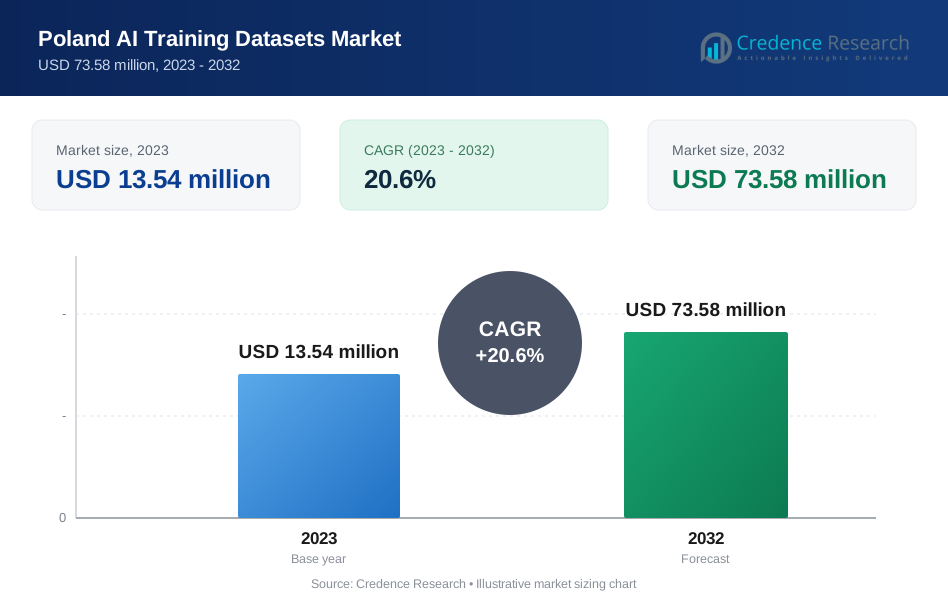
The Poland AI Training Datasets Market is projected to grow from USD 13.54 million in 2023 to an estimated USD 73.58 million by 2032, with a compound annual growth rate (CAGR) of 20.6% from 2024 to 2032. This growth is driven by the increasing adoption of AI technologies across various industries, coupled with the rise in demand for high-quality, labeled datasets necessary for training AI models.
Key drivers of the market include the growing need for efficient AI systems in sectors like healthcare, finance, and manufacturing, as well as the increasing emphasis on machine learning and deep learning techniques. Additionally, there is a rise in demand for labeled datasets due to the complexity and accuracy required for AI model development. Moreover, technological advancements in data collection, annotation, and processing are contributing to market growth. Trends such as the integration of AI in various business processes and the increasing importance of data privacy are also influencing the market.
Geographically, Poland is seeing substantial investments in AI, with a particular focus on enhancing AI infrastructure and data availability. The presence of key market players in the region, such as DataRobot, Google AI, and Amazon Web Services, is also accelerating market growth. These players are focusing on the development of scalable AI solutions and data platforms, helping Poland position itself as a leader in the AI training datasets market in Central and Eastern Europe.
Market Insights
- The Poland AI Training Datasets Market is expected to grow from USD 13.54 million in 2023 to USD 73.58 million by 2032, with a CAGR of 20.6% from 2024 to 2032.
- The increasing adoption of AI technologies across industries such as healthcare, finance, and manufacturing is driving the demand for high-quality, labeled datasets.
- Technological advancements in machine learning and deep learning techniques, coupled with the need for accurate and comprehensive datasets, are fueling market growth.
- Data privacy regulations, such as GDPR, present challenges by requiring datasets to be compliant, limiting access to sensitive information for AI training.
- Data scarcity and quality issues in certain sectors, particularly in specialized industries like healthcare and automotive, hinder the availability of diverse datasets for AI models.
- Central Poland, particularly Warsaw, holds the largest market share due to its tech infrastructure, research institutions, and presence of global AI players.
- Southern Poland (e.g., Kraków and Katowice) is a growing hub for AI development, contributing significantly to the demand for AI datasets in sectors like healthcare and automotive.
Market Drivers
Rising Demand for AI-Driven Solutions Across Various Industries
The increasing adoption of artificial intelligence (AI) across multiple sectors is one of the primary drivers of the Poland AI Training Datasets Market. Industries such as healthcare, finance, automotive, manufacturing, and retail are rapidly integrating AI technologies into their operations to enhance productivity, efficiency, and decision-making capabilities. AI-driven solutions are being used for a wide range of applications, including predictive analytics, automation, image recognition, natural language processing, and autonomous vehicles. However, the effectiveness of AI models largely depends on the availability of high-quality training datasets. These datasets are critical for training machine learning models and ensuring their accuracy. As businesses across Poland recognize the immense potential of AI, there is a growing demand for diverse, high-quality training datasets that can be used to improve the performance of AI applications. Consequently, this demand is fueling market growth and driving the need for specialized data solutions, including labeled datasets that can help AI systems learn and function optimally. For instance, a recent report highlighted that the adoption of AI technologies among Polish companies surged by 36% over the past year, making Poland the fastest-growing nation in AI integration within the EU. This growth is particularly pronounced in sectors such as defense, where 71% of companies are utilizing AI for applications like quality control and cybersecurity. Similarly, 47% of manufacturing firms have adopted AI solutions to enhance process automation and customer service, leading to improved operational efficiency.
Advancements in AI and Machine Learning Techniques
Technological advancements in AI and machine learning techniques, particularly in areas like deep learning, have significantly increased the demand for large-scale, well-structured training datasets. Deep learning models, which are particularly powerful in image and speech recognition tasks, require vast amounts of data to achieve high performance. This need for large, accurate datasets has become even more pronounced with the growing use of AI in complex applications such as medical imaging, autonomous driving, and financial modeling. In Poland, where the AI research and development landscape is rapidly evolving, machine learning researchers and organizations are consistently pushing the boundaries of what AI can achieve. As a result, there is a heightened demand for datasets that not only provide sufficient data volume but also ensure a high level of annotation accuracy. This trend drives the market for AI training datasets, as organizations in Poland are looking to harness the full potential of these advanced machine learning techniques. For Instance, Numerous Polish startups are leveraging AI across diverse fields, including healthcare and education. For example, companies are utilizing AI to improve children's physiotherapy and optimize agricultural practices. This trend not only showcases the versatility of AI applications but also highlights the increasing recognition of its potential to drive innovation and economic growth within the country.
Government Initiatives and Investments in AI Infrastructure
The Polish government’s active role in fostering the development of AI technologies and infrastructure is another significant driver of the Poland AI Training Datasets Market. Poland has recognized the strategic importance of AI in its economic development and has implemented various initiatives to boost the adoption and implementation of AI technologies. These initiatives include the development of national AI strategies, funding for AI research projects, and the creation of AI innovation hubs. The Polish government is also partnering with private sector players to support AI research and training datasets creation. Additionally, European Union funds aimed at enhancing AI capabilities in Central and Eastern Europe have further accelerated the growth of AI in Poland. These investments are enabling local companies and research institutions to access advanced AI technologies and datasets, which are crucial for training AI models. Government-backed initiatives that foster collaboration between AI developers, data scientists, and industry experts contribute to the development of robust training datasets that are both comprehensive and accurate. As the government continues to invest in AI infrastructure, the demand for training datasets will continue to rise, propelling the market's expansion. For Instance, the Polish government is actively investing in AI infrastructure, with plans to establish an Artificial Intelligence Factory at AGH University in Kraków. This initiative, which involves an investment of nearly PLN 70 million, aims to bolster collaboration within the European AI ecosystem and enhance local research capabilities. Such developments underscore the strategic importance placed on AI by both public and private sectors in Poland.
Increased Focus on Data Privacy and Regulation Compliance
Data privacy concerns and regulatory compliance requirements are critical factors shaping the Poland AI Training Datasets Market. With growing awareness about data security and privacy laws, particularly the General Data Protection Regulation (GDPR) in the European Union, organizations must ensure that their AI training datasets are not only comprehensive but also comply with stringent data privacy standards. In Poland, as part of the European Union, there is a strong emphasis on adhering to GDPR guidelines, which impose strict rules on data collection, storage, and processing. As a result, there is a growing need for datasets that are carefully curated to meet these regulations, ensuring that individuals’ privacy rights are protected. Moreover, the ability to maintain data privacy while building high-quality datasets is a major concern for businesses and researchers working with sensitive data, such as personal health information or financial records. This has led to the rise of data anonymization techniques, secure data handling practices, and the use of synthetic datasets that help mitigate privacy risks. These factors are not only driving the demand for compliant datasets but also prompting innovations in how datasets are generated, processed, and maintained.
Market Trends
Growth of Synthetic Datasets to Overcome Data Scarcity and Privacy Issues
A significant trend in the Poland AI Training Datasets Market is the growing use of synthetic datasets. Traditional AI training relies heavily on real-world data, which can sometimes be scarce or difficult to obtain, especially in niche applications such as medical diagnostics, autonomous vehicles, or sensitive financial data. Additionally, there are concerns surrounding data privacy, particularly when working with personal or sensitive information, which may be subject to stringent regulations like the General Data Protection Regulation (GDPR) in the European Union. Synthetic datasets, generated using algorithms that simulate realistic data patterns, are becoming increasingly popular as an alternative. These datasets allow businesses and researchers to train AI models without compromising privacy or dealing with the challenges of obtaining high volumes of real-world data. In Poland, as in other parts of Europe, the development and utilization of synthetic datasets are rapidly gaining momentum. This trend is particularly relevant for industries such as healthcare and finance, where data privacy is paramount. By using synthetic data, organizations can avoid the risk of violating privacy regulations while still training powerful AI models. This shift towards synthetic datasets is expected to continue, driven by advancements in artificial data generation technologies and the need for privacy-conscious AI development. For instance, in the healthcare sector, where patient data is crucial yet sensitive, synthetic datasets enable researchers to train AI models without compromising individual privacy. This approach not only adheres to stringent regulations like GDPR but also allows for the creation of diverse datasets that can simulate various medical scenarios, thus enhancing the robustness of AI applications in diagnostics and treatment planning.
Focus on Data Labeling and Annotation to Enhance Dataset Quality
Another prominent trend in the Poland AI Training Datasets Market is the increasing emphasis on data labeling and annotation. While data collection is an essential step in building AI training datasets, ensuring the accuracy and quality of the labeled data is equally critical. Inaccurate or poorly labeled data can significantly hinder the performance of AI models, especially in complex tasks like image recognition, sentiment analysis, and natural language processing. As AI technologies advance, there is a growing recognition that the quality of the data being fed into AI models is just as important as the quantity. This has led to a surge in demand for high-quality labeled datasets, particularly in specialized industries like healthcare, automotive, and e-commerce. In Poland, businesses are increasingly investing in robust data labeling platforms and partnerships with data annotation service providers to ensure that their datasets meet high standards of accuracy. Additionally, there is an increasing use of AI-assisted data labeling tools that automate parts of the labeling process, reducing the time and cost associated with manual annotation while maintaining the integrity of the data. This trend is expected to grow as the complexity of AI models increases and the need for high-quality datasets becomes more pronounced. For example, companies in Poland are investing in AI-assisted data annotation tools that can efficiently label vast amounts of unstructured data, such as images and text. These tools significantly reduce the time and cost associated with manual labeling while ensuring high accuracy. This trend is particularly evident in industries like automotive and e-commerce, where precise data labeling is essential for training effective machine learning models.
Collaboration Between Private and Public Sectors to Build AI Ecosystem
A notable trend in Poland’s AI Training Datasets Market is the growing collaboration between public and private sector players to build a more robust AI ecosystem. The Polish government has placed a high priority on advancing AI technologies and has launched several initiatives to encourage innovation and attract investment in AI research and development. These efforts include national AI strategies, funding opportunities for AI startups, and partnerships with the European Union for collaborative research projects. In response, private companies, including tech giants and local startups, are actively engaging in research and development partnerships with academic institutions, government bodies, and non-profit organizations to create better AI training datasets. These collaborations help to expand access to high-quality datasets while fostering innovation in AI technologies. For example, the Polish government has supported several AI-focused research hubs, which facilitate the sharing of datasets and expertise among various stakeholders. Public-private partnerships are also instrumental in addressing data privacy concerns, ensuring that AI models are trained using data that complies with local and European regulations. This collaboration between sectors is expected to accelerate the growth of the Poland AI Training Datasets Market by ensuring a continuous supply of reliable datasets and fostering an environment conducive to AI innovation. For instance, several AI-focused research hubs have been established to facilitate the sharing of datasets and expertise among stakeholders. This collaborative environment not only enhances access to high-quality datasets but also addresses privacy concerns by ensuring compliance with local regulations during data utilization. Government initiatives aimed at promoting AI research and development have led to partnerships with academic institutions and private companies, creating a synergistic effect that drives advancements in AI technology across various sectors.
Rise of AI-Powered Data Annotation Tools and Platforms
The increasing demand for large and high-quality datasets has spurred the development and adoption of AI-powered data annotation tools in Poland. These tools leverage AI and machine learning algorithms to automate and optimize the process of data labeling and annotation. While manual data annotation is time-consuming and resource-intensive, AI-powered tools can speed up the process and improve the consistency and accuracy of labeled data. These tools are capable of processing vast amounts of unstructured data, such as images, videos, and text, to automatically identify and label objects or entities, making them ideal for use in complex applications like autonomous driving, facial recognition, and medical imaging. AI-powered annotation tools can also assist in ensuring that data adheres to compliance standards, such as GDPR, by anonymizing sensitive information before labeling it. The proliferation of AI-based data annotation platforms in Poland is driving the market by enabling organizations to scale their data labeling processes and create datasets more efficiently. The continuous improvement of these AI-powered tools will further enhance the quality of AI training datasets, contributing to the development of more accurate and effective AI models.
Market Challenges
Data Privacy and Regulatory Compliance Concerns
One of the primary challenges facing the Poland AI Training Datasets Market is the strict data privacy regulations, particularly the General Data Protection Regulation (GDPR) in the European Union. As Poland is part of the EU, businesses and research organizations must comply with these comprehensive laws that govern the collection, processing, and storage of personal data. AI training often requires access to vast amounts of data, including sensitive information such as personal health records, financial data, or demographic details. However, obtaining and using such data is increasingly complex due to GDPR's stringent requirements. Organizations must ensure that any data used in AI models is anonymized, stored securely, and processed with explicit consent from individuals. Failure to adhere to these regulations can result in severe penalties and reputational damage. This regulatory burden often limits access to high-quality, real-world data, making it more challenging for companies in Poland to develop effective AI training datasets. Furthermore, as AI research and applications evolve, ensuring compliance with the ever-changing landscape of data privacy laws remains a significant hurdle.
Data Scarcity and Quality Issues
Another challenge in the Poland AI Training Datasets Market is the scarcity and quality of available data. Many AI applications, particularly in niche sectors like healthcare, finance, and autonomous vehicles, require large, diverse, and accurately labeled datasets to train models effectively. However, obtaining such datasets can be difficult, as many industries have limited access to high-quality data or face significant challenges in curating and annotating data accurately. In some cases, datasets may be incomplete, biased, or unrepresentative, which can negatively affect the performance and fairness of AI models. Moreover, in sectors like healthcare, where patient data is often sensitive, obtaining sufficient quantities of data while ensuring privacy compliance becomes even more challenging. For companies in Poland, this data scarcity and quality issue presents a significant barrier to creating effective AI training datasets, hindering the ability to build accurate, reliable AI systems that can provide value across industries.
Market Opportunities
Expanding AI Adoption in Key Industries
A significant market opportunity for the Poland AI Training Datasets Market lies in the growing adoption of AI technologies across key industries such as healthcare, finance, automotive, and manufacturing. As these sectors increasingly incorporate AI into their operations, the demand for high-quality, well-labeled datasets will continue to rise. In healthcare, for example, AI-driven solutions such as diagnostic tools, personalized medicine, and medical imaging require large volumes of accurately labeled data to train machine learning models. Similarly, industries like automotive are relying on AI for the development of autonomous driving systems, which also depend heavily on diverse and high-quality training datasets. As Poland continues to position itself as a hub for AI research and development in Central and Eastern Europe, local businesses and startups in these sectors are poised to benefit from advanced AI solutions. This trend opens up significant opportunities for dataset providers, data labeling services, and companies offering synthetic data solutions to meet the growing demand for AI training datasets.
Government Support and EU Funding for AI Innovation
Poland’s commitment to advancing AI through government initiatives and European Union funding presents another promising opportunity for the AI Training Datasets Market. The Polish government has recognized AI as a key driver of economic growth and technological innovation, leading to the development of national AI strategies and funding programs aimed at accelerating AI adoption. Additionally, Poland benefits from EU-backed projects and collaborations, which provide financial support and resources for AI research, development, and the creation of datasets. These initiatives create a favorable environment for market growth, with an increasing number of public-private partnerships focused on improving AI infrastructure and dataset accessibility. For businesses involved in dataset generation and management, this supportive ecosystem presents valuable opportunities to expand their reach and contribute to Poland’s AI-driven transformation.
Market Segmentation Analysis
By Type
The Poland AI Training Datasets Market can be segmented by dataset type into Text, Audio, Image, Video, and Others. Text datasets are the dominant segment, as they are widely used in natural language processing (NLP) applications such as chatbots, sentiment analysis, and machine translation, which are essential for training AI models to understand and generate human language. Image datasets are also significant, with applications in image recognition, facial recognition, and autonomous vehicles. These datasets are crucial for training deep learning models reliant on visual data. Audio and Video datasets are increasingly used in voice recognition systems, automated transcription services, and video analytics, with audio datasets being particularly important for speech-to-text applications and virtual assistants. The Others segment includes specialized datasets like sensor data, which are used in industries such as automotive (for autonomous driving) and healthcare (for medical diagnostics).
By Deployment Mode
The Poland AI Training Datasets Market is also segmented by deployment mode into On-Premises and Cloud. Cloud-based deployment is gaining popularity due to its scalability, cost-effectiveness, and ease of access to large-scale datasets. Cloud platforms allow organizations to store and process massive datasets efficiently, making them ideal for businesses looking to scale up their AI initiatives. In contrast, On-premises deployment is preferred by organizations with strict data privacy and security requirements. While on-premises solutions provide better control over sensitive data, they often come with higher costs related to infrastructure setup, maintenance, and ongoing management.
Segments
Based on Type
- Text
- Audio
- Image
- Video
- Others (Sensor and Geo)
Based on Deployment Mode
- On-Premises
- Cloud
Based on End-Users
- IT and Telecommunications
- Retail and Consumer Goods
- Healthcare
- Automotive
- BFSI
- Others (Government and Manufacturing)
Based on Region
- Central Poland
- Southern Poland
- Western Poland
- Eastern Poland
Regional Analysis
Central Poland (40%)
Central Poland, particularly Warsaw, holds the largest share of the AI Training Datasets Market, accounting for approximately 40% of the market share. Warsaw is the capital and economic hub of Poland, hosting a significant portion of the country's tech startups, AI research centers, and global tech companies. The city is home to several leading universities and research institutions, which foster AI development and provide a steady supply of talent for AI-related projects. The demand for AI training datasets in Warsaw is driven by the extensive use of AI technologies across industries such as finance, retail, healthcare, and IT. Furthermore, the presence of large international players like Google AI, Microsoft, and IBM contributes to the region’s dominance in the AI space. The ongoing investments in AI infrastructure and the availability of robust digital ecosystems also position Warsaw as a leader in dataset generation and utilization for AI applications.
Southern Poland (25%)
Southern Poland, including cities like Kraków and Katowice, contributes around 25% to the Poland AI Training Datasets Market. This region is known for its rapidly growing AI and technology sectors, driven by strong academic institutions and a thriving startup ecosystem. Kraków, in particular, is a key player in AI research, attracting both local and international companies focused on AI solutions. The demand for training datasets in Southern Poland is significant, especially in areas such as healthcare, automotive, and IT. The presence of major universities and research hubs specializing in AI makes this region a critical contributor to dataset creation. Furthermore, the growing importance of AI in sectors like manufacturing and logistics in Southern Poland fuels the demand for specialized datasets, particularly those related to automation, predictive maintenance, and supply chain management.
Key players
- Alphabet Inc Class A
- Appen Ltd
- Cogito Tech
- com Inc
- Microsoft Corp
- Allegion PLC
- Lionbridge
- SCALE AI
- Sama
- Deep Vision Data
Competitive Analysis
The Poland AI Training Datasets Market is highly competitive, with a mix of global tech giants and specialized AI dataset providers. Alphabet Inc Class A, Amazon.com Inc, and Microsoft Corp lead the market due to their extensive AI research, vast datasets, and technological infrastructure. These companies not only dominate in terms of dataset availability but also invest significantly in AI innovations and cloud-based solutions. Appen Ltd, Lionbridge, and Sama focus on data labeling and annotation services, offering high-quality labeled datasets for a variety of industries. SCALE AI is emerging as a strong player by providing AI-powered data labeling tools that improve efficiency and scalability. Cogito Tech, Allegion PLC, and Deep Vision Data serve niche markets, offering tailored datasets in sectors such as cybersecurity, manufacturing, and visual data applications. The market remains dynamic, with continuous technological advancements and increasing collaboration between these key players.
Recent Developments
- In January 2025, Alphabet Inc. announced an expansion of its Google Cloud services in Poland, focusing on AI and machine learning capabilities. This initiative aims to provide local businesses with access to advanced AI training datasets and tools, fostering innovation and enhancing data-driven decision-making across various sectors.
- In December 2024, Appen Ltd launched a new partnership with Polish tech companies to enhance data annotation services. This collaboration is designed to improve the quality of training datasets for AI applications in natural language processing and computer vision, specifically tailored for the European market.
- In November 2024, Amazon Web Services (AWS) introduced new features in its SageMaker Ground Truth service, enhancing dataset labeling capabilities for Polish developers. This update aims to facilitate the creation of high-quality training datasets for various AI applications, including predictive analytics and machine learning.
- On November 28, 2024, Microsoft announced a significant commitment to AI skilling in Poland, aiming to equip one million people with competencies in artificial intelligence by the end of 2025. The initiative includes free training programs and resources available through the Microsoft AI Skills Navigator platform.
- In January 2025, Allegion PLC launched an initiative in Poland focused on developing AI-driven security solutions. As part of this effort, the company is investing in creating specialized training datasets to enhance the effectiveness of its security technologies.
- In February 2025, SCALE AI revealed a new collaboration with Polish startups to enhance data labeling processes. This partnership focuses on improving the efficiency and accuracy of creating training datasets for machine learning applications across multiple industries.
Market Concentration and Characteristics
The Poland AI Training Datasets Market is moderately concentrated, with a mix of large multinational corporations and specialized dataset providers. Major global players such as Alphabet Inc Class A, Amazon.com Inc, and Microsoft Corp dominate the market due to their vast resources, technological infrastructure, and ability to leverage extensive datasets for AI model training. However, the market also features a growing presence of specialized companies like Appen Ltd, Lionbridge, and Sama, which focus on data labeling and annotation services to meet industry-specific needs. The market characteristics include strong competition in data quality, scalability, and compliance with regulatory standards like GDPR. Furthermore, the demand for high-quality, diverse datasets is growing as AI adoption expands across various sectors, prompting both large and niche players to innovate continuously. As AI applications diversify, the market is becoming increasingly dynamic, with new entrants and collaborations shaping its future trajectory.
Report Coverage
The research report offers an in-depth analysis based on Type, Deployment Mode, End User and Region. It details leading market players, providing an overview of their business, product offerings, investments, revenue streams, and key applications. Additionally, the report includes insights into the competitive environment, SWOT analysis, current market trends, as well as the primary drivers and constraints. Furthermore, it discusses various factors that have driven market expansion in recent years. The report also explores market dynamics, regulatory scenarios, and technological advancements that are shaping the industry. It assesses the impact of external factors and global economic changes on market growth. Lastly, it provides strategic recommendations for new entrants and established companies to navigate the complexities of the market.
Future Outlook
- The demand for AI training datasets will expand as industries like healthcare, automotive, and finance increasingly adopt AI-driven solutions to enhance operational efficiency and innovation.
- The use of synthetic datasets will grow to address data scarcity and privacy concerns, offering a viable alternative to real-world data while ensuring regulatory compliance.
- AI-powered data annotation tools will continue to evolve, enabling faster and more accurate labeling of datasets, thus improving the efficiency of AI training processes.
- Poland’s government will continue to invest in AI research and infrastructure, creating a favorable environment for the development of high-quality datasets and driving market growth.
- Niche sectors such as agriculture, logistics, and cybersecurity will see increased demand for specialized AI training datasets, leading to more targeted solutions for these industries.
- Partnerships between government bodies, research institutions, and private companies will foster innovation, ensuring access to diverse and high-quality datasets for AI model development.
- As data privacy regulations like GDPR remain critical, companies will prioritize creating datasets that adhere to privacy standards, ensuring secure AI model training processes.
- The adoption of cloud-based platforms for dataset storage and processing will continue to rise, offering greater scalability and accessibility to AI developers in Poland.
- European Union funding initiatives for AI projects in Poland will further stimulate growth in the AI training datasets market, accelerating research and development in AI technologies.
- New AI applications in areas such as personalized medicine, autonomous vehicles, and smart cities will drive the need for large and diverse datasets, expanding market opportunities.
Request a Free Sample
Fill in your details and we'll send you a free sample report.
- Sample data tables & charts
- Research methodology
Need a Custom Version of This Report?
Tailor the scope, geography, or segments to your exact requirements.
- Custom geography or segment scope
- Direct access to our analyst team
Frequently Asked Questions
What is the market size of the Poland AI Training Datasets Market in 2023 and 2032?
What is driving the growth of the Poland AI Training Datasets Market?
Which industries are most contributing to the demand for AI training datasets in Poland?
How does data privacy impact the AI training datasets market in Poland?
What role do global companies like Amazon and Google play in Poland's AI dataset market?
Table of Content
Chapter 1. Report Introduction
- 1.1 Report Description & Purpose
- 1.1.1 Report Title & Market Definition
- 1.1.2 Unique Selling Propositions (USP) & Key Differentiators
- 1.1.3 Value Proposition for Stakeholders
- 1.2 Research Objectives
- 1.2.1 Market Sizing Objectives (Volume & Revenue) (Volume Where Applicable)
- 1.2.2 Segmentation Objectives
- 1.2.3 Competitive Intelligence Objectives
- 1.2.4 Forecast & Scenario Objectives
- 1.3 Report Scope
- 1.3.1 Poland AI Training Datasets Scope – Segments & Subsegments Covered
- 1.3.2 Geographic Scope – Selected Country & Subnational Markets Covered
- 1.3.3 Historical Period, Base Year & Forecast Period (2023; forecast to 2032)
- 1.3.4 Inclusions & Exclusions
- 1.4 Industry Classification & Applicable Codes
- 1.5 Currency, Measurement Units & Valuation Basis
- 1.6 Target Stakeholders
- 1.7 Limitations & Assumptions
Chapter 2. Executive Summary
- 2.1 Poland AI Training Datasets Snapshot
- 2.1.1 Market Size – Historical (2023) & Forecast (2023-2032) (2023: USD 13.54 million → 2032: USD 73.58 million)
- 2.1.2 Volume & Revenue – National Totals (Volume Where Applicable)
- 2.1.3 Key Market Highlights – Top Five Facts
- 2.2 Poland AI Training Datasets Segmentation Snapshot
- 2.2.1 Market Split by Subnational Area – 2023 vs. 2032
- 2.3 Competitive Snapshot
- 2.3.1 Top 10 Players by Revenue Share – 2023
- 2.3.2 Top 10 Players by Volume Share – 2023 (Volume Where Applicable)
- 2.3.3 Recent Strategic Developments (18-Month Summary)
- 2.4 Key Investment Highlights & Strategic Conclusions
Chapter 3. Poland AI Training Datasets Dynamics & Industry Analysis
- 3.1 Market Overview & Context
- 3.1.1 Poland AI Training Datasets Position in the Broader Industry Value Chain
- 3.1.2 Demand Structure & Purchasing Dynamics
- 3.1.3 Market Maturity & Development Stage Across Domestic Markets
- 3.2 Poland AI Training Datasets Drivers
- 3.3 Poland AI Training Datasets Restraints & Challenges
- 3.4 Poland AI Training Datasets Opportunities
- 3.5 Porter's Five Forces Analysis
- 3.5.1 Threat of New Entrants
- 3.5.2 Bargaining Power of Suppliers
- 3.5.3 Bargaining Power of Buyers
- 3.5.4 Threat of Substitutes
- 3.5.5 Competitive Rivalry – Intensity Assessment
- 3.6 Poland AI Training Datasets Value Chain Analysis
- 3.6.1 Upstream – Key Inputs, Resources & Suppliers
- 3.6.1.1 Key Input/Resource 1
- 3.6.1.2 Key Input/Resource 2
- 3.6.1.3 Key Input/Resource 3
- 3.6.2 Midstream – Core Operations & Value Creation
- 3.6.2.1 Operating Model & Process Overview
- 3.6.2.2 Key Operating Locations & Capabilities by Company
- 3.6.3 Downstream – Market Channels & End Users
- 3.6.3.1 Direct Sales & Customer Engagement Channels
- 3.6.3.2 Indirect Sales, Intermediaries & Partner Channels
- 3.6.4 Value Chain Profitability Analysis
- 3.6.1 Upstream – Key Inputs, Resources & Suppliers
- 3.7 PESTEL Analysis
- 3.7.1 Political Factors
- 3.7.2 Economic Factors
- 3.7.3 Social Factors
- 3.7.4 Technological Factors
- 3.7.5 Environmental Factors
- 3.7.6 Legal Factors
- 3.8 Poland AI Training Datasets Supply Chain Analysis
- 3.8.1 Critical Input & Resource Availability Risk Assessment
- 3.8.2 Supplier & Operational Concentration Risk (Geographic Exposure)
- 3.8.3 Supply & Service Disruption Impact Analysis
- 3.9 National & Subnational Regulatory Landscape
Note: The regulatory and policy landscape section covers regulations based on their applicability to the market, Poland AI Training Datasets category, geography, and scope of the study. Only regulatory frameworks with a material impact on operations, compliance, trade, sustainability, or market access are analyzed in detail.
Chapter 4. Key Investment Pockets & Opportunity Analysis
- 4.1 Poland AI Training Datasets Attractiveness Analysis
- 4.1.1 By Subnational Area – Investment Attractiveness Matrix (Market Size × CAGR)
- 4.2 Absolute Revenue Growth Opportunity
- 4.2.1 By Subnational Area – Absolute Revenue Growth Through 2032
- 4.3 Incremental Demand Opportunity
- 4.3.1 By Subnational Area – Incremental Demand Through 2032
- 4.3.2 Segment – Incremental Demand
- 4.4 Emerging Submarket Opportunity Deep Dive (Subject to Applicability)
- 4.5 Priority Domestic Market Opportunity Scorecards
- 4.5.1 Priority Domestic Market 1
- 4.5.2 Priority Domestic Market 2
- 4.5.3 Priority Domestic Market 3
- 4.5.4 Priority Domestic Market 4
Note: Domestic market scorecards cover relevant states, provinces, territories, cities, or economic zones within the selected country. Numbered entries are populated with market names suited to the national administrative structure and research scope. Geographic share tables use one consistent, nonoverlapping set of areas.
Chapter 5. Poland AI Training Datasets Cross-Border Trade & Market Access Analysis
- 5.1 National Trade & International Partner Overview
- 5.1.1 Export Value by Destination Country (2023)
- 5.1.2 Export Volume by Destination Country (2023) (Where Applicable)
- 5.1.3 Import Value by Source Country (2023)
- 5.1.4 Import Volume by Source Country (2023) (Where Applicable)
- 5.1.5 National & Partner-Country Trade Balances (2023)
- 5.2 Export Analysis – Segment
- 5.2.1 Category 1 (Applicable Classification Code)
- 5.2.2 Category 2 (Applicable Classification Code)
- 5.2.3 Category 3 (Applicable Classification Code)
- 5.2.4 Category 4 (Applicable Classification Code)
- 5.2.5 Category 5 (Applicable Classification Code)
- 5.3 Import Analysis – Segment
- 5.3.1 Category 1 (Applicable Classification Code)
- 5.3.2 Category 2 (Applicable Classification Code)
- 5.3.3 Category 3 (Applicable Classification Code)
- 5.3.4 Category 4 (Applicable Classification Code)
- 5.3.5 Category 5 (Applicable Classification Code)
- 5.4 Cross-Border Pricing & Transaction Benchmarks
- 5.4.1 Export Pricing – Segment & Destination Country
- 5.4.2 Import Pricing – Segment & Source Country
- 5.4.3 Price Trends (2023)
- 5.5 Key Cross-Border Trade & Delivery Routes
- 5.5.1 Cross-Border Trade/Delivery Route 1
- 5.5.2 Cross-Border Trade/Delivery Route 2
- 5.5.3 Cross-Border Trade/Delivery Route 3
- 5.5.4 Cross-Border Trade/Delivery Route 4
- 5.5.5 Cross-Border Trade/Delivery Route 5
- 5.6 Trade Policy & Market Access Impact Assessment
- 5.6.1 Tariff & Non-Tariff Barriers
- 5.6.2 National Participation in Regional Trade & Economic Frameworks
- 5.6.3 Bilateral & Multilateral Trade Agreements
- 5.6.4 Cross-Border Operating, Licensing & Localization Requirements
Note: This chapter covers international trade relevant to Poland AI Training Datasets in the selected country. Exports are analyzed by destination and imports by source. Domestic interregional flows are excluded from international trade totals. Goods, services, and digital offerings use applicable classifications; volume and route analyses apply only where meaningful.
Chapter 6. Competitive Landscape & Company Benchmarking
- 6.1 Poland AI Training Datasets Concentration & Structure
- 6.1.1 Herfindahl-Hirschman Index (HHI) – the historical period vs. 2023
- 6.1.2 Leading, Mid-Sized & Emerging Player Structure
- 6.1.3 Multinational, National & Local Player Dynamics
- 6.2 Poland AI Training Datasets Share Analysis – 2023
- 6.2.1 National Revenue Share by Company
- 6.2.2 National Volume Share by Company (Volume Where Applicable)
- 6.2.3 Company Revenue Share by Subnational Area
- 6.2.4 Market Share Evolution (the historical period vs. 2023)
- 6.2.5 Company Market Share by Key Segment
- 6.2.6 Company Market Share by Customer Group
- 6.3 Operating Scale, Capacity & Infrastructure Analysis
- 6.3.1 National Operating Scale & Supply Capacity
- 6.3.2 Resource Utilization & Operating Efficiency
- 6.3.3 Output, Service Delivery & Activity Metrics
- 6.3.4 Operating Footprint & Infrastructure Map
- 6.3.5 Planned Operational & Capacity Expansion
- 6.4 Poland AI Training Datasets Competitive Benchmarking Matrix
- 6.4.1 Revenue, Growth, Profitability & Operating Metric Comparison
- 6.4.2 Channel Revenue Mix
- 6.4.3 Revenue Exposure Across Domestic Markets
- 6.4.4 R&D Intensity
- 6.4.5 Sustainability Maturity
- 6.5 Strategic Developments in Poland AI Training Datasets (Last 24 Months)
- 6.5.1 Mergers, Acquisitions & Divestments
- 6.5.2 New Products, Services & Solutions in Poland AI Training Datasets
- 6.5.3 Operational & Infrastructure Expansions
- 6.5.4 Strategic Alliances, Joint Ventures & Partnerships
- 6.5.5 Distribution Expansion & Market Entry
- 6.5.6 Sustainability & ESG Initiatives
- 6.6 Competitive Strategy Mapping
- 6.6.1 Leader, Challenger, Follower & Niche Classification
- 6.6.2 Pricing Strategy Comparison
- 6.6.3 Channel Strategy Matrix
Note: Strategic developments are included based on their materiality and the availability of reliable information.
Chapter 7. Poland AI Training Datasets – By Sales & Delivery Channel
- 7.1 Segment Overview
- 7.1.1 Volume & Revenue Split by Channel (2023 & 2032) (Volume Where Applicable)
- 7.1.2 Channel Mix Evolution (2023-2032)
Chapter 8. Subnational Market Analysis – Country Overview
- 8.1 Domestic Geographic Market Overview
- 8.1.1 Subnational Volume Share (Where Applicable)
- 8.1.2 Subnational Revenue Share
- 8.1.3 Market Volume by Subnational Area (Where Applicable)
- 8.1.4 Market Revenue by Subnational Area
- 8.1.5 Subnational Forecasts Through 2032
- 8.2 Cross-Area Segment Analysis Within the Country
- 8.2.1 By Sales & Delivery Channel
- 8.2.2 By Competitive Positioning & Price Tier
Chapter 9. Poland AI Training Datasets – Priority Domestic Market 1
Chapter 10. Poland AI Training Datasets – Priority Domestic Market 2
Chapter 11. Poland AI Training Datasets – Priority Domestic Market 3
Chapter 12. Poland AI Training Datasets – Priority Domestic Market 4
Chapter 13. Poland AI Training Datasets Company Profiles
- 13.1 [Company 01]
- 13.1.1 Company Overview
- 13.1.2 Key Management Personnel
- 13.1.3 Products & Services Portfolio
- 13.1.4 Financial Performance
- 13.1.5 Domestic Market Focus & Local Operating Presence
- 13.1.6 Recent Developments & Strategic Initiatives
Note: The company profile list is preliminary and may change based on research findings, market developments, data availability, and client requirements.
Chapter 14. Appendices
- Appendix A – List of Abbreviations & Acronyms
- Appendix B – Industry Classification Code Reference – Full Series
- Appendix C – Supply, Output & Operating Capacity Data Tables
- Appendix D – End-Use & Demand Base Tables
- Appendix E – Demand, Adoption & Usage Assumptions
- Appendix F – Pricing & Revenue Metric Reference Tables
- Appendix G – Company Operations & Infrastructure Database
- Appendix H – Cross-Border Trade & Activity Data Tables (Where Applicable)
- Appendix I – Regulatory Summary Tables
- Appendix J – Primary Research Participant List (Anonymized)
- Appendix K – Primary Research Questionnaire Framework
- Appendix L – Data Sources & Bibliography
- Appendix M – Market Size Divergence & Source Comparison
Chapter 15. Research Methodology
- 15.1 Research Framework & Philosophy
- 15.2 Secondary Research – Sources, Hierarchy & Data Extraction
- 15.3 Data Modeling – National Market Sizing & Subnational Allocation
- 15.4 Primary Research – Stakeholder Framework, LOI & Sample Sizes
- 15.5 Forecast Methodology – Regression, Scenario & Sensitivity Analysis
- 15.6 Quality Control – Four-Layer Validation Framework
- 15.7 Limitations & Standard Assumptions
- 15.8 Disclaimer
