
| REPORT ATTRIBUTE | DETAILS |
|---|---|
| Historical Period | 2020-2023 |
| Base Year | 2024 |
| Forecast Period | 2025-2032 |
| Synthetic Data Generation Market Size 2024 | USD 315 Million |
| Synthetic Data Generation Market, CAGR | 46.2% |
| Synthetic Data Generation Market Size 2032 | USD 6,574.9 Million |
Market Overview:
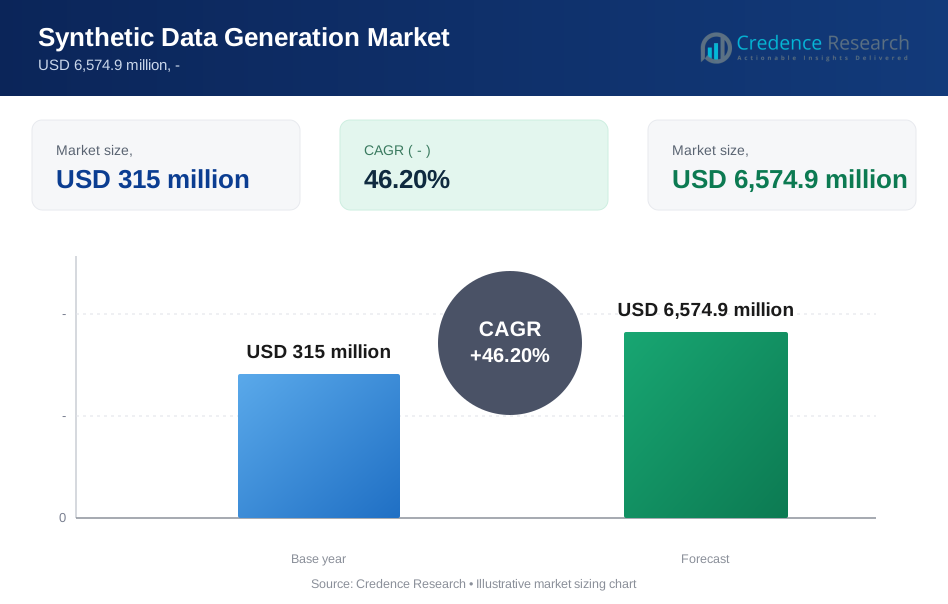
The Synthetic Data Generation Market is projected to grow from USD 315 million in 2024 to USD 6,574.9 million by 2032, at a 46.2% CAGR, driven by increasing demand for AI model training and data privacy solutions.
The synthetic data generation market is experiencing rapid growth, driven by increasing demand for high-quality, diverse, and privacy-compliant data for AI model training and analytics. Organizations across industries, including healthcare, finance, and autonomous systems, are leveraging synthetic data to overcome challenges related to data scarcity, bias, and regulatory constraints. The rising adoption of generative AI, advancements in machine learning algorithms, and growing concerns over data privacy regulations such as GDPR and CCPA are further fueling market expansion. Additionally, synthetic data is proving crucial in augmenting real-world datasets, enabling more robust AI models while reducing costs and risks associated with real data collection. The integration of synthetic data with digital twin technology and its application in cybersecurity, fraud detection, and predictive analytics are emerging as key trends. As enterprises seek scalable and compliant data solutions, the synthetic data generation market is poised for substantial growth, with innovation and investment driving further advancements in this space.
The synthetic data generation market exhibits varied growth across regions, with North America leading at 38% market share in 2024, driven by strong AI adoption and regulatory frameworks like CCPA. Europe follows with 27% market share, where GDPR accelerates the demand for privacy-compliant data solutions. Asia-Pacific holds 23% of the market share, with China, Japan, and India investing heavily in AI technologies. The Rest of the World, including Latin America, the Middle East, and Africa, accounts for 12%, with steady growth driven by AI and smart city initiatives. Key players such as Microsoft, Google, IBM, AWS, NVIDIA, OpenAI, and others are expanding their presence across these regions, capitalizing on regional opportunities and driving innovation to meet sector-specific demands. These companies are focusing on strategic partnerships and product innovations to enhance their market positions globally.
Market Insights:
- The synthetic data generation market is projected to grow from USD 315 million in 2024 to USD 6,574.9 million by 2032, with a 46.2% CAGR.
- Increasing demand for high-quality, diverse, and privacy-compliant data for AI model training and analytics is driving market growth.
- Rising adoption of generative AI, machine learning advancements, and regulatory frameworks like GDPR and CCPA further fuel market expansion.
- Synthetic data enables organizations to overcome data scarcity, bias, and regulatory challenges across industries such as healthcare, finance, and autonomous systems.
- The integration of synthetic data with digital twin technology is revolutionizing industries like manufacturing, healthcare, and smart cities.
- North America leads the market with a 38% share, followed by Europe at 27%, and Asia-Pacific at 23% in 2024.
- The Rest of the World holds 12% of the market share, with increasing AI, cybersecurity, and smart city initiatives driving growth.
Market Drivers:
Increasing Demand for AI and Machine Learning Training Data:
The rapid expansion of artificial intelligence (AI) and machine learning (ML) applications has significantly increased the demand for high-quality, diverse, and unbiased datasets. Synthetic data generation provides a scalable and cost-effective solution for training AI models without the limitations of real-world data, such as scarcity, privacy risks, and labeling costs. For instance, IBM is leveraging synthetic data to enhance model accuracy, reduce biases, and accelerate AI development, driving market growth.
Rising Concerns Over Data Privacy and Compliance:
Stringent data privacy regulations, including GDPR, CCPA, and HIPAA, are pushing organizations to seek alternative methods for data utilization. Synthetic data, which mimics real-world data without exposing sensitive information, offers a compliant and secure way to handle data for analytics, testing, and AI training. For example, healthcare organizations like Mayo Clinic are adopting synthetic data solutions to mitigate risks associated with data breaches and regulatory non-compliance. As enterprises focus on mitigating risks associated with data breaches and regulatory non-compliance, the adoption of synthetic data solutions is surging across industries such as healthcare, finance, and retail.
Cost-Effective and Scalable Data Generation:
Traditional data collection methods are time-consuming, expensive, and often limited in scope. Synthetic data generation enables businesses to create large volumes of labeled data at a fraction of the cost, reducing dependency on real-world data acquisition. For instance, autonomous vehicle companies like Waymo are using synthetic data to generate extensive datasets for training their AI systems. This advantage is particularly beneficial for industries requiring extensive datasets, such as autonomous vehicles, robotics, and fraud detection. By providing scalable, on-demand data generation, synthetic data solutions are becoming an essential tool for companies aiming to optimize AI performance while minimizing operational costs.
Advancements in Generative AI and Digital Twin Technology:
Innovations in generative AI, including deep learning and reinforcement learning, are enhancing the capabilities of synthetic data generation. Additionally, the integration of synthetic data with digital twin technology is revolutionizing industries such as manufacturing, healthcare, and smart cities. For example, Siemens is integrating synthetic data with digital twin technology to enable realistic simulations and predictive analytics in manufacturing. These advancements enable realistic simulations, predictive analytics, and improved decision-making, further driving market expansion. As AI and digital transformation initiatives continue to evolve, synthetic data is poised to play a crucial role in shaping the future of data-driven innovation.
Market Trends:
Integration of Generative AI for Enhanced Data Synthesis:
The synthetic data generation market is witnessing a surge in the adoption of generative AI models, such as Generative Adversarial Networks (GANs) and Variational Autoencoders (VAEs). These advanced AI techniques enable the creation of highly realistic and diverse datasets that closely mimic real-world data while eliminating privacy risks. For example, companies like NVIDIA are leveraging generative AI to improve model accuracy, reduce biases, and enhance data diversity across various applications, including computer vision, natural language processing, and predictive analytics.
Growing Adoption in Regulated Industries:
Industries with strict regulatory requirements, such as healthcare, finance, and insurance, are increasingly utilizing synthetic data to address compliance challenges. By generating anonymized yet statistically representative data, organizations can conduct AI training, testing, and data analysis without violating privacy laws like GDPR and HIPAA. For instance, pharmaceutical companies like Pfizer are adopting synthetic data solutions to conduct medical research while ensuring data security and confidentiality. This trend is particularly prominent in medical research, fraud detection, and risk assessment, where data security and confidentiality remain critical concerns.
Expansion of Digital Twin Technology:
The rise of digital twin technology is driving the demand for synthetic data to create virtual replicas of real-world systems, processes, and environments. Industries such as manufacturing, smart cities, and autonomous vehicles are integrating synthetic data with digital twins to enhance simulations, predictive maintenance, and decision-making. For example, companies like Siemens are integrating synthetic data with digital twins to enable realistic simulations and predictive analytics in manufacturing. This trend is enabling businesses to optimize operations, improve efficiency, and reduce costs while mitigating risks associated with real-world experimentation.
Increased Focus on Bias Mitigation and Fair AI:
As AI adoption grows, addressing bias and ensuring fairness in machine learning models have become key priorities. Synthetic data is playing a crucial role in mitigating biases by enabling the generation of balanced and representative datasets. For instance, tech companies like Google are utilizing synthetic data to create equitable AI systems that promote fairness, inclusivity, and transparency. Companies are actively utilizing synthetic data to create equitable AI systems that promote fairness, inclusivity, and transparency, aligning with ethical AI development standards.
Market Challenges Analysis:
Data Realism and Model Accuracy Limitations:
One of the key challenges in the synthetic data generation market is ensuring that artificially generated datasets maintain a high level of realism and accuracy. While advancements in generative AI have significantly improved the quality of synthetic data, achieving near-perfect representation of real-world data remains complex and requires continuous refinement. In fields such as healthcare, finance, and autonomous systems, even minor inaccuracies in synthetic data can lead to flawed AI model predictions, misinterpretations, and suboptimal decision-making, which can have significant consequences. For instance, if the real data sample used to generate synthetic data is too small or not representative, the synthetic data will inherit these limitations, leading to potential inaccuracies in downstream AI models. Organizations must continuously refine their synthetic data models to ensure statistical integrity, domain-specific relevance, and alignment with real-world behaviors while reducing inherent biases. Additionally, validating synthetic data against real datasets is essential, yet it requires extensive computational resources, domain expertise, and advanced evaluation metrics, adding complexity and cost to its adoption. Without proper validation and rigorous testing, synthetic data may fail to provide the expected benefits, limiting its practical usability in real-world applications.
Regulatory Uncertainty and Ethical Concerns:
The regulatory landscape surrounding synthetic data is still evolving, creating uncertainty for organizations looking to integrate synthetic datasets into their AI and analytics workflows. While synthetic data helps organizations comply with stringent data privacy regulations like GDPR, HIPAA, and CCPA, concerns remain regarding its ethical implications, regulatory acceptance, and potential misuse. For instance, the ability to generate realistic yet artificial datasets raises questions about data authenticity, consent, and accountability, particularly in critical applications such as healthcare diagnostics, financial decision-making, and legal proceedings. Moreover, biases inherent in the real data used to generate synthetic datasets can persist or even be amplified, leading to unintended consequences in AI-driven applications and discriminatory outcomes. Addressing these regulatory and ethical challenges requires industry-wide collaboration, clear legal frameworks, and the development of best practices to ensure the responsible use of synthetic data while maintaining transparency, accountability, and trust among stakeholders. Organizations must also invest in bias detection, fairness assessments, and compliance strategies to ensure the ethical and secure deployment of synthetic data solutions.
Market Opportunities:
The synthetic data generation market presents significant growth opportunities as industries increasingly adopt AI-driven solutions that require high-quality, diverse, and scalable datasets. Organizations in sectors such as healthcare, finance, retail, and autonomous systems are leveraging synthetic data to overcome challenges related to data privacy, scarcity, and regulatory compliance. With stringent data protection laws such as GDPR and HIPAA limiting access to real-world data, synthetic data offers a viable alternative for AI model training, software testing, and analytics without compromising security or compliance. Additionally, businesses are recognizing the cost and efficiency benefits of synthetic data, which enables faster and more flexible data generation compared to traditional data collection methods. As AI and machine learning applications continue to expand, the demand for synthetic data solutions is expected to rise, driving innovation and investments in the sector.
Furthermore, the integration of synthetic data with emerging technologies such as digital twins, generative AI, and edge computing is opening new market opportunities. Digital twin technology, which creates virtual replicas of physical systems, relies heavily on synthetic data for real-time simulations and predictive modeling in industries like manufacturing, healthcare, and smart cities. Similarly, advancements in generative AI models, such as GANs and VAEs, are enhancing the realism and applicability of synthetic data, making it more valuable for businesses seeking to optimize AI performance. The growing focus on ethical AI and bias mitigation is also creating demand for synthetic data solutions that can generate fair and representative datasets. As enterprises prioritize data-driven decision-making and innovation, synthetic data is poised to become a critical enabler of AI development, unlocking new business models and revenue streams in the coming years.
Market Segmentation Analysis:
By Offering
The synthetic data generation market by offering is segmented into software and services. Synthetic data generation software enables businesses to create, modify, and validate artificial datasets for AI training, testing, and analytics. Services include consulting, integration, and managed solutions that help organizations effectively implement synthetic data strategies while ensuring compliance and optimal data utilization.
By Data Type
By data type, the market is categorized into text, image, video, and tabular data. Text-based synthetic data supports NLP applications, while image and video synthetic data enhance computer vision models used in industries like autonomous driving and healthcare. Tabular synthetic data is crucial for structured datasets in finance, fraud detection, and risk assessment, allowing businesses to generate statistically accurate yet privacy-compliant information.
By Verticals
The verticals segment includes healthcare, BFSI, retail, automotive, IT & telecom, and others. Healthcare and BFSI are leading adopters due to strict data privacy regulations. Retail and automotive leverage synthetic data for customer insights and autonomous vehicle simulations, respectively. IT & telecom sectors use synthetic data to enhance cybersecurity, predictive analytics, and network optimization, driving innovation across multiple industries.
Segments:
Based on Offering:
- Solution/Platform
- Services
Based on Data Type:
- Tabular Data
- Text data
- Image and Video Data
- Others
Based on Application:
- AI/ML Training and Development
- Test Data Management
- Data analytics and visualization
- Enterprise Data Sharing
- Others
Based on Vertical:
- BFSI
- Healthcare & Life sciences
- Retail & E-commerce
- Automotive & Transportation
- Government & Defense
- IT and ITeS
- Manufacturing
- Other Verticals
Based on the Geography:
- North America
- U.S.
- Canada
- Mexico
- Europe
- Germany
- France
- U.K.
- Italy
- Spain
- Rest of Europe
- Asia Pacific
- China
- Japan
- India
- South Korea
- South-east Asia
- Rest of Asia Pacific
- Latin America
- Brazil
- Argentina
- Rest of Latin America
- Middle East & Africa
- GCC Countries
- South Africa
- Rest of the Middle East and Africa
Regional Analysis:
North America
North America dominates the synthetic data generation market, accounting for 38% of the market share in 2024. The region's strong presence in AI, machine learning, and data privacy regulations drives significant demand for synthetic data solutions. The United States leads the market, with tech giants and AI startups heavily investing in synthetic data for training models while ensuring compliance with data protection laws such as CCPA. The financial sector, healthcare, and autonomous vehicle industries are key contributors to market growth, leveraging synthetic data to enhance AI-driven applications. Additionally, government initiatives supporting AI innovation and cybersecurity are further fueling market expansion in this region.
Europe
Europe holds a 27% market share in 2024, driven by stringent data privacy regulations such as GDPR, which restricts real data usage and accelerates synthetic data adoption. The region is witnessing strong demand across healthcare, banking, and manufacturing sectors, where organizations require privacy-compliant data solutions for AI and analytics. The UK, Germany, and France are leading markets, with increasing investments in AI research and digital transformation. European financial institutions and healthcare organizations are actively adopting synthetic data to comply with regulatory frameworks while enhancing AI capabilities. Additionally, collaborations between government bodies, research institutions, and AI firms are fostering innovation in synthetic data generation technologies.
Asia-Pacific
Asia-Pacific accounts for 23% of the market share in 2024, with rapid adoption of AI, big data analytics, and digital transformation initiatives. Countries such as China, Japan, and India are investing heavily in synthetic data technologies to support AI advancements in sectors like e-commerce, autonomous vehicles, and telecommunications. China leads the region, driven by its AI dominance and government-backed initiatives promoting synthetic data for AI model training. In Japan and South Korea, synthetic data is being utilized in robotics, manufacturing, and healthcare to enhance AI applications while mitigating data privacy risks. The region’s increasing focus on AI-driven automation and innovation is expected to drive further growth in synthetic data adoption.
Rest of the World
The rest of the world, including Latin America, the Middle East, and Africa, holds a 12% market share in 2024. While adoption is slower compared to other regions, growing interest in AI, cybersecurity, and smart city initiatives is driving demand for synthetic data. Countries in the Middle East, particularly the UAE and Saudi Arabia, are investing in AI-powered digital transformation, increasing the need for synthetic data solutions. In Latin America, financial institutions and healthcare providers are exploring synthetic data to enhance AI-driven decision-making while maintaining compliance with emerging data privacy regulations. As AI adoption increases in these regions, the demand for synthetic data is expected to grow steadily.
Key Player Analysis:
- Tonic (US)
- Databricks (US)
- MOSTLY AI (Austria)
- OpenAI (US)
- Mphasis (India)
- Broadcom (US)
- Sogeti (France)
- NVIDIA (US)
- AWS (US)
- IBM (US)
Competitive Analysis:
The synthetic data generation market is highly competitive, with leading players such as Microsoft, Google, IBM, AWS, NVIDIA, OpenAI, Informatica, Broadcom, Sogeti, Mphasis, Databricks, MOSTLY AI, and Tonic. These companies are actively investing in advanced technologies like generative AI, machine learning, and data privacy solutions to develop cutting-edge synthetic data tools. Microsoft is leveraging its Azure cloud infrastructure to enable seamless deployment of synthetic data solutions at scale. Microsoft, Google, and AWS lead the cloud infrastructure space, enabling seamless deployment of synthetic data solutions at scale. OpenAI and NVIDIA are driving innovation in generative AI models, enhancing the realism and applicability of synthetic datasets across various industries. Meanwhile, companies like MOSTLY AI and Tonic focus on providing tailored synthetic data solutions with strong emphasis on privacy and compliance. As industries across healthcare, finance, and automotive continue to adopt AI, these players are expanding their market presence through strategic partnerships, acquisitions, and product innovations to maintain a competitive edge.
Recent Developments:
- In March 2024, Hazy Limited and Unbanx LLC joined forces to introduce an ethical data cooperative comprised of synthetically generated financial transaction data. This marked a step forward for the company in ethical data monetization.
- In March 2023, Hazy Limited, a key player in the synthetic data generation market, raised USD 9 million in Series A funding. This solidified its position as the synthetic data provider and enabled it to explore the potential of generative AI.
- In May 2023, Databricks acquired Okera, a data governance platform with a focus on AI. the acquisition will enable Databricks to expose additional APIs that its own data governance partners will be able to use to provide solutions to their customers.
- In January 2023, Microsoft entered into a multi-billion-dollar partnership with OpenAI to accelerate the development of AI technology. The partnership aims to democratize AI and make it accessible to everyone. The partnership has already yielded impressive results, including the development of GPT-3.
Market Concentration & Characteristics:
The synthetic data generation market is characterized by a moderate to high concentration, with several key players dominating the landscape. Major companies such as Microsoft, Google, IBM, AWS, and NVIDIA are leading the market, driving innovation through advancements in AI, machine learning, and data privacy solutions. These players are strategically investing in research and development to enhance the capabilities of synthetic data generation technologies, aiming to address challenges related to data scarcity, bias, and compliance with regulations. As the market continues to grow, the competition is intensifying, with both large enterprises and specialized startups seeking to capitalize on the increasing demand for high-quality, privacy-compliant data. Additionally, partnerships, collaborations, and mergers and acquisitions are common strategies to strengthen market positions and expand service offerings. The market is also witnessing regional fragmentation, with North America, Europe, and Asia-Pacific being the primary growth hubs.
Report Coverage:
The research report offers an in-depth analysis based on Offering, Data Type, Vertical, Application and Geography. It details leading market players, providing an overview of their business, product offerings, investments, revenue streams, and key applications. Additionally, the report includes insights into the competitive environment, SWOT analysis, current market trends, as well as the primary drivers and constraints. Furthermore, it discusses various factors that have driven market expansion in recent years. The report also explores market dynamics, regulatory scenarios, and technological advancements that are shaping the industry. It assesses the impact of external factors and global economic changes on market growth. Lastly, it provides strategic recommendations for new entrants and established companies to navigate the complexities of the market.
Future Outlook:
- The synthetic data generation market is expected to continue its rapid growth.
- Increasing adoption of AI and machine learning technologies across industries will drive demand for synthetic data solutions.
- Privacy-compliant data generation will become more critical as data privacy regulations like GDPR and CCPA tighten globally.
- Advances in generative AI and deep learning will significantly improve the quality and realism of synthetic data.
- The integration of synthetic data with digital twin technology will transform sectors such as manufacturing, healthcare, and smart cities.
- The market will witness growing demand from industries like healthcare, finance, automotive, and retail for model training and analytics.
- New startups focused on synthetic data solutions will emerge, intensifying competition and fostering innovation in the market.
- Cost-effective and scalable data generation solutions will make synthetic data increasingly accessible to businesses of all sizes.
- The trend of ethical AI and bias-free data will lead to more stringent validation methods and fairness assessments in synthetic data generation.
- Global expansion will continue, with significant market growth in Asia-Pacific, Latin America, and the Middle East.
Request a Free Sample
Fill in your details and we'll send you a free sample report.
- Sample data tables & charts
- Research methodology
Market Dynamics
Demand for AI/ML Training Data
The proliferation of AI and machine learning applications across industries is driving the need for large, high-quality, and diverse datasets. Synthetic data generation enables organizations to efficiently create scalable datasets for model training, overcoming limitations of real-world data such as scarcity, privacy risks, and high labeling costs.
Stringent Data Privacy and Compliance Regulations
Global regulations like GDPR, CCPA, and HIPAA are making it increasingly difficult for organizations to use real data for analytics and AI. Synthetic data provides a privacy-compliant alternative, allowing businesses to innovate and analyze data without exposing sensitive information or violating regulatory requirements.
Cost-Effective and Scalable Data Generation
Traditional data collection and labeling are expensive and time-consuming, especially for industries requiring vast and varied datasets. Synthetic data generation offers a cost-effective, scalable solution, enabling rapid creation of labeled data for applications such as autonomous vehicles, fraud detection, and robotics.
Advancements in Generative AI and Digital Twin Integration
Breakthroughs in generative AI models (e.g., GANs, VAEs) and the integration of synthetic data with digital twin technology are enhancing the realism and utility of synthetic datasets. This enables more accurate simulations, predictive analytics, and decision-making in sectors like manufacturing, healthcare, and smart cities.
Bias Mitigation and Fair AI Development
As organizations prioritize ethical AI, synthetic data is increasingly used to generate balanced and representative datasets, helping to reduce bias in machine learning models. This supports the development of fair, transparent, and inclusive AI systems, which is becoming a critical requirement for regulatory and reputational reasons.
Need a Custom Version of This Report?
Tailor the scope, geography, or segments to your exact requirements.
- Custom geography or segment scope
- Direct access to our analyst team
Frequently Asked Questions
What drives the growth of the synthetic data generation market?
Which industries use synthetic data generation?
What role do regulations play in this market?
Which regions lead in market share?
Who are the major players in the market?
Table of Content
Chapter 1 Market Segmentation
- 1.1 Segmentation Framework
- 1.1.1 Product and Service Classification
- 1.1.2 Application and End-Use Classification
- 1.1.3 Technology and Solution Classification
- 1.1.4 Customer and Distribution Channel Classification
- 1.1.5 Geographic Segmentation
- 1.1.6 Market Segment Definitions and Boundaries
- 1.2 By Offering
- 1.2.1 Solution/Platform
- 1.2.2 Services
- 1.3 By Vertical
- 1.3.1 BFSI
- 1.3.2 Healthcare & Life Sciences
- 1.3.3 Retail & E-commerce
- 1.3.4 Automotive & Transportation
- 1.3.5 Government & Defense
- 1.3.6 IT and ITeS
- 1.3.7 Manufacturing
- 1.3.8 Other Verticals
- 1.4 By Data Type
- 1.4.1 Tabular Data
- 1.4.2 Text Data
- 1.4.3 Image and Video Data
- 1.4.4 Others
- 1.5 By Application
- 1.5.1 AI/ML Training and Development
- 1.5.2 Test Data Management
- 1.5.3 Data Analytics and Visualization
- 1.5.4 Enterprise Data Sharing
- 1.5.5 Others
Chapter 2 Introduction
- 2.1 Report Objectives and Scope
- 2.2 Product Definition and Industry Terminology
- 2.3 Market Inclusions and Exclusions
- 2.4 Research Process
- 2.4.1 Primary Research and Expert Interviews
- 2.4.2 Secondary Research and Source Review
- 2.4.3 Top-Down and Bottom-Up Estimation
- 2.4.4 Data Triangulation and Verification
- 2.5 Market Size Measurement Basis
- 2.5.1 2024: USD 315 million → 2032: USD 6,574.9 million
- 2.6 Historical and Forecast Reference Periods
- 2.6.1 Base Year: 2024
- 2.6.2 Forecast Period: 2024-2032
- 2.7 Research Assumptions and Limitations
Chapter 3 Executive Summary
- 3.1 Market Snapshot and Key Findings
- 3.2 Base-Year Market Size, 2024
- 3.3 Forecast Market Size, 2032
- 3.4 Revenue and Volume Growth Outlook
- 3.5 Key Demand and Supply Indicators
- 3.6 Leading Market Segments
- 3.7 Fastest-Growing Market Opportunities
- 3.8 Regional Performance Highlights
- 3.9 Technology and Industry Transformation
- 3.10 Competitive Landscape Summary
- 3.11 Analyst View and Strategic Implications
Chapter 4 Global Synthetic Data Generation Market Trends and Developments
- 4.1 Historical Industry Development
- 4.2 Recent Market Trends and Developments
- 4.3 Demand and Customer Behavior Trends
- 4.4 Technology and Product Innovation
- 4.5 Artificial Intelligence, Automation and Digitalization
- 4.6 Local Manufacturing and Supply Chain Realignment
- 4.7 Industry Partnerships, Mergers and Acquisitions
- 4.8 Sustainability and Circular Economy Developments
- 4.9 Government and Private Sector Investment Trends
- 4.10 Emerging Business Models and Commercialization
- 4.11 Industry Developments and Announcements
Chapter 5 Global Synthetic Data Generation Market Production, Supply and Demand Analysis
- 5.1 Demand Trend and Consumption Analysis
- 5.2 Demand Forecast, 2024-2032
- 5.3 Production and Output Trend
- 5.4 Production and Output Forecast, 2024-2032
- 5.5 Installed Capacity and Capacity Utilization
- 5.6 Company-Wise Production Plants and Statistics
- 5.6.1 Installed Production Capacity
- 5.6.2 Actual Production
- 5.6.3 Planned Capacity and Expansion Targets
- 5.7 Supply Chain Structure and Procurement Trends
- 5.8 Supply-Demand Gap and Bottlenecks
- 5.9 Import Dependence and Sourcing Structure
- 5.10 Contract Manufacturing and Outsourcing
- 5.11 Regional Supply and Demand Concentration
Chapter 6 Global Synthetic Data Generation Market Pricing Analysis
- 6.1 Pricing Structure and Measurement
- 6.2 Historical Pricing Trends
- 6.3 Pricing Outlook, 2024-2032
- 6.4 Average Selling Price and Unit Economics
- 6.5 Pricing by Product and Market Segment
- 6.6 Geographic Pricing Differences
- 6.7 Key Input, Energy, Labor and Logistics Costs
- 6.8 Contract Pricing and Purchasing Models
- 6.9 Pricing Sensitivity and Competitive Positioning
- 6.10 Price, Margin and Profitability Implications
Chapter 7 Global Synthetic Data Generation Market Dynamics
- 7.1 Market Growth Drivers
- 7.1.1 Demand-Side Drivers
- 7.1.2 Technology and Innovation Drivers
- 7.1.3 Infrastructure and Investment Drivers
- 7.1.4 Regulatory and Policy Drivers
- 7.2 Market Restraints
- 7.2.1 Cost and Affordability Constraints
- 7.2.2 Technology and Adoption Barriers
- 7.2.3 Supply Chain and Operational Constraints
- 7.3 Market Challenges
- 7.3.1 Competitive Pressure and Margin Erosion
- 7.3.2 Skills, Infrastructure and Implementation Gaps
- 7.4 Emerging Market Opportunities
- 7.5 Market Dynamics Impact and Time-Horizon Assessment
Chapter 8 Global Synthetic Data Generation Value Chain Analysis
- 8.1 Industry Value Chain Overview
- 8.2 Upstream Suppliers and Critical Inputs
- 8.3 Technology and Component Providers
- 8.4 Manufacturing or Service Delivery
- 8.5 Distribution, Channel Partners and Integrators
- 8.6 Downstream Applications and End Users
- 8.7 Value Addition and Profit Pools
- 8.8 Vertical Integration and Outsourcing
- 8.9 Supplier Concentration and Risk
- 8.10 Supply Chain Localization and Resilience
Chapter 9 Global Synthetic Data Generation Market Regulations and Policies
- 9.1 Relevant Laws, Standards and Compliance Frameworks
- 9.2 Product, Service, Safety and Quality Requirements
- 9.3 Government Policies, Incentives and Subsidies
- 9.4 Imports, Exports and Trade Barriers
- 9.5 Public Procurement and Local Content Requirements
- 9.6 Environmental and Sustainability Compliance
- 9.7 Data Protection, AI and Cybersecurity Compliance
- 9.8 Upcoming Policy Changes and Market Implications
Chapter 10 Global Synthetic Data Generation Market Hotspots and Opportunities
- 10.1 Market Opportunity Mapping and Growth Hotspots
- 10.2 High-Growth Applications and Customer Groups
- 10.3 Underserved Markets and White-Space Opportunities
- 10.4 Emerging Technology and Product Opportunities
- 10.5 New Capacity and Investment Hotspots
- 10.6 Market Entry and Expansion Opportunities
- 10.7 Distribution and Partnership Opportunities
- 10.8 Near-Term and Long-Term Commercial Potential
- 10.9 Opportunity Attractiveness and Execution Risks
Chapter 11 Global Synthetic Data Generation Market Outlook, 2024-2032
- 11.1 Market Size and Analysis
- 11.1.1 Revenue (Market Measurement: 2024: USD 315 million → 2032: USD 6,574.9 million)
- 11.1.2 Market Volume and Quantity Sold
- 11.1.3 Historical Market Size
- 11.1.4 Base-Year Market Size, 2024
- 11.2 Market Forecast, 2024-2032
- 11.2.1 Revenue Forecast to 2032
- 11.2.2 Volume Forecast to 2032
- 11.2.3 CAGR and Year-on-Year Growth
- 11.2.4 Incremental Revenue Opportunity
- 11.3 Forecast Assumptions and Scenario Analysis
- 11.3.1 Base-Case Forecast
- 11.3.2 Optimistic and Conservative Scenarios
- 11.3.3 Technology, Pricing and Policy Sensitivities
- 11.4 Market Attractiveness and Growth Outlook
Chapter 12 Global Synthetic Data Generation Market Segmentation and Outlook
- 12.1 Segmentation Summary and Market Shares, 2024
- 12.2 Largest and Fastest-Growing Segments
- 12.3 By Offering - Market Size and Forecast, 2024-2032
- 12.3.1 Segment Definition and Scope
- 12.3.2 Historical Market Size
- 12.3.3 Revenue Forecast, 2024-2032
- 12.3.4 Volume Forecast, 2024-2032
- 12.3.5 Base-Year Market Share, 2024
- 12.3.6 Segment CAGR and Growth Drivers
- 12.3.7 Subsegment Market Size and Forecast
- 12.3.7.1 Solution/Platform
- 12.3.7.2 Services
- 12.3.8 Subsegment Pricing and Adoption Trends
- 12.3.9 Leading Suppliers and Competition
- 12.3.10 Regional Demand and Opportunities
- 12.4 By Vertical - Market Size and Forecast, 2024-2032
- 12.4.1 Segment Definition and Scope
- 12.4.2 Historical Market Size
- 12.4.3 Revenue Forecast, 2024-2032
- 12.4.4 Volume Forecast, 2024-2032
- 12.4.5 Base-Year Market Share, 2024
- 12.4.6 Segment CAGR and Growth Drivers
- 12.4.7 Subsegment Market Size and Forecast
- 12.4.7.1 BFSI
- 12.4.7.2 Healthcare & Life Sciences
- 12.4.7.3 Retail & E-commerce
- 12.4.7.4 Automotive & Transportation
- 12.4.7.5 Government & Defense
- 12.4.7.6 IT and ITeS
- 12.4.7.7 Manufacturing
- 12.4.7.8 Other Verticals
- 12.4.8 Subsegment Pricing and Adoption Trends
- 12.4.9 Leading Suppliers and Competition
- 12.4.10 Regional Demand and Opportunities
- 12.5 By Data Type - Market Size and Forecast, 2024-2032
- 12.5.1 Segment Definition and Scope
- 12.5.2 Historical Market Size
- 12.5.3 Revenue Forecast, 2024-2032
- 12.5.4 Volume Forecast, 2024-2032
- 12.5.5 Base-Year Market Share, 2024
- 12.5.6 Segment CAGR and Growth Drivers
- 12.5.7 Subsegment Market Size and Forecast
- 12.5.7.1 Tabular Data
- 12.5.7.2 Text Data
- 12.5.7.3 Image and Video Data
- 12.5.7.4 Others
- 12.5.8 Subsegment Pricing and Adoption Trends
- 12.5.9 Leading Suppliers and Competition
- 12.5.10 Regional Demand and Opportunities
- 12.6 By Application - Market Size and Forecast, 2024-2032
- 12.6.1 Segment Definition and Scope
- 12.6.2 Historical Market Size
- 12.6.3 Revenue Forecast, 2024-2032
- 12.6.4 Volume Forecast, 2024-2032
- 12.6.5 Base-Year Market Share, 2024
- 12.6.6 Segment CAGR and Growth Drivers
- 12.6.7 Subsegment Market Size and Forecast
- 12.6.7.1 AI/ML Training and Development
- 12.6.7.2 Test Data Management
- 12.6.7.3 Data Analytics and Visualization
- 12.6.7.4 Enterprise Data Sharing
- 12.6.7.5 Others
- 12.6.8 Subsegment Pricing and Adoption Trends
- 12.6.9 Leading Suppliers and Competition
- 12.6.10 Regional Demand and Opportunities
- 12.7 Segment Growth Comparison
- 12.8 Segment Attractiveness and Priority Matrix
Chapter 13 Global Synthetic Data Generation End-Use and Application Market Outlook
- 13.1 End-Use Industry and Customer Demand Structure
- 13.2 Leading Applications and Customer Groups
- 13.3 End-Use Market Size, Share and Forecast
- 13.4 Major End-Use Industry Deep Dives
- 13.4.1 Customer Requirements and Use Cases
- 13.4.2 Demand and Replacement Cycles
- 13.4.3 Technical and Regulatory Considerations
- 13.4.4 Purchasing and Procurement Models
- 13.4.5 Leading Vendors and Distribution Channels
- 13.4.6 Forecast and Commercial Opportunities
- 13.5 Emerging Applications and Cross-Segment Demand
- 13.6 End-Use Industry Investment Priorities
Chapter 14 Global Synthetic Data Generation Geographic Market Outlook, 2024-2032
- 14.1 Regional Market Size and Share, 2024
- 14.2 Regional Market Forecast, 2024-2032
- 14.3 Regional Pricing, Production and Demand Differences
- 14.4 North America
- 14.4.1 United States
- 14.4.2 Canada
- 14.4.3 Mexico
- 14.5 Europe
- 14.5.1 Germany
- 14.5.2 France
- 14.5.3 Italy
- 14.5.4 United Kingdom
- 14.5.5 Spain
- 14.5.6 Poland
- 14.5.7 Russia
- 14.5.8 Netherlands
- 14.5.9 Belgium
- 14.5.10 Sweden
- 14.5.11 Denmark
- 14.5.12 Norway
- 14.5.13 Rest of Europe
- 14.6 Asia Pacific
- 14.6.1 China
- 14.6.2 India
- 14.6.3 Japan
- 14.6.4 South Korea
- 14.6.5 Thailand
- 14.6.6 Indonesia
- 14.6.7 Vietnam
- 14.6.8 Malaysia
- 14.6.9 Australia
- 14.6.10 Rest of Asia Pacific
- 14.7 Latin America
- 14.7.1 Brazil
- 14.7.2 Argentina
- 14.7.3 Colombia
- 14.7.4 Chile
- 14.7.5 Rest of Latin America
- 14.8 Middle East
- 14.8.1 Saudi Arabia
- 14.8.2 United Arab Emirates
- 14.8.3 Turkey
- 14.8.4 Israel
- 14.8.5 Iran
- 14.8.6 Rest of the Middle East
- 14.9 Africa
- 14.9.1 South Africa
- 14.9.2 Egypt
- 14.9.3 Nigeria
- 14.9.4 Morocco
- 14.9.5 Rest of Africa
- 14.10 Regional Investment, Policy and Supply Chain Differences
- 14.11 Regional Competitive Landscape
- 14.12 Geographic Growth Hotspots
Chapter 15 Global Synthetic Data Generation Technology, Innovation and Sustainability Outlook
- 15.1 Technology Landscape and Maturity
- 15.2 Product, Process and Service Innovation
- 15.3 AI, Automation and Digital Tools in the Industry
- 15.4 Technology Adoption and Performance Benchmarking
- 15.5 Innovation Pipeline and R&D Investment
- 15.6 Patent and Intellectual Property Trends
- 15.7 Energy Efficiency and Resource Management
- 15.8 Sustainability, Recycling and Circularity
- 15.9 Technology Roadmap, 2024-2032
- 15.10 Risks of Obsolescence and Technology Substitution
Chapter 16 Global Synthetic Data Generation Market Key Strategic Imperatives
- 16.1 Growth and Market Entry Priorities
- 16.2 High-Return Products and Segments
- 16.3 Pricing, Profitability and Cost Optimization
- 16.4 Technology Investment and Product Differentiation
- 16.5 Supply Chain Localization and Resilience
- 16.6 Distribution and Customer Acquisition
- 16.7 Partnership, Acquisition and Capacity Strategy
- 16.8 Regional Expansion Priorities
- 16.9 Short-, Medium- and Long-Term Actions
Chapter 17 Competition Outlook
- 17.1 Industry Competition Characteristics
- 17.2 Market Structure and Concentration
- 17.3 Market Share and Competitive Positioning, 2024
- 17.4 Company-Wise Revenue and Product Benchmarking
- 17.5 Production and Service Capacity Benchmarking
- 17.6 Technology, Pricing and Differentiation
- 17.7 Regional Footprint and Distribution Strength
- 17.8 Mergers, Acquisitions and Strategic Alliances
- 17.9 New Entrants and Competitive Threats
- 17.10 Porter's Five Forces and Industry Attractiveness
- 17.11 Competitive Outlook, 2024-2032
Chapter 18 Company Profiles
- 18.1 Company Coverage and Selection Criteria
- 18.2 Microsoft
- 18.2.1 Business Description
- 18.2.2 Company Ownership and Geographic Presence
- 18.2.3 Product and Service Portfolio
- 18.2.4 Manufacturing and Operating Footprint
- 18.2.5 Production Capacity and Expansion Plans
- 18.2.6 Financial Performance and Investment
- 18.2.7 Market Share and Competitive Position
- 18.2.8 Technology and Innovation Capabilities
- 18.2.9 Strategic Alliances or Partnerships
- 18.2.10 Recent Developments
- 18.2.11 Growth Strategy and Outlook
- 18.3 Google
- 18.4 IBM
- 18.5 AWS
- 18.6 NVIDIA
- 18.7 OpenAI
- 18.8 Databricks
- 18.9 MOSTLY AI
- 18.10 Tonic
- 18.11 Mphasis
- 18.12 Other Relevant Market Participants
Note: Every listed company is profiled on the structure shown under the first company. The company list is preliminary and may change based on research findings, market developments, data availability and client requirements.
Chapter 19 Disclaimer
- 19.1 Research and Forecast Disclaimer
- 19.2 Data Source and Estimation Limitations
Note: The depth of individual sections depends on data availability for this market. Volume, capacity, trade and other unit-based metrics are included where applicable.

